
Oct 20, 2026/11 min readFinancial Services
How to Build a Modern Fraud Detection Platform with Online ML
Fraud is a growing problem that continues to drive compliance expenses higher year after year. Achieving regulatory compliance with effective, real-time fraud prevention has quickly become one of the financial services industry's most critical and expensive challenges. Enterprise-ready fraud detection relies on robust machine learning infrastructure that continuously and dynamically analyzes transaction patterns, flags anomalies and adapts to emerging threats in real time.
Catching bad actors before a transaction clears requires production-grade infrastructure designed to detect fraud in milliseconds. In this blog post, we'll dive into how Snowflake ML addresses these real-time challenges by unifying streaming features, low-latency model serving and MLOps on a single data and ML platform. In particular, we highlight the advantages of using Snowflake’s Online Feature Store (now generally available) to productionize fraud detection workflows by serving features in less than 10ms and enabling subsecond feature freshness from real time streaming events.
Why it's hard: The real challenges
For all financial institutions, there are three core challenges that make the fraud detection problem difficult to address at enterprise scale: latency of results for real-time transactions, the ever-changing landscape of fraud tactics, and the comprehensive security and governance requirements of sensitive customer and financial data.
Addressing the latency problem
Most institutions struggle to detect fraud in real time because legacy batch pipelines and static rules engines cannot evaluate live transactions against fresh behavioral data within millisecond SLAs. Stopping fraud requires an architecture capable of delivering subsecond feature freshness. This includes using stream feature views to continuously ingest live events (e.g. logins, transactions) into a low-latency serving layer. During inference time, real-time feature views need to dynamically compute request-level metrics (e.g. comparing current transaction spend to a customer's historical baseline).
Monitoring model performance over time
Fraud models degrade as adversaries adapt. What detected synthetic identity fraud last quarter may miss the next generation of attacks this quarter. This is model drift — and most institutions discover it too late. Enterprises that are successful at monitoring performance over time have fully managed ML systems that are easy to develop, iterate and promote relevant features and models to production to seamlessly adapt to changes in the business.
Keeping all data secure and governed
For most legacy fraud detection systems, inference calls often send data to an external platform. Egress leads to governance risk level that may be unacceptable for regulated financial institutions. End-to-end data lineage and data governance are must-haves for a production fraud detection system that includes sensitive data.
These business challenges stem directly from traditional ML infrastructure limitations — and solving them requires an end-to-end, real-time ML platform built for enterprise scale.
What successful fraud detection looks like
VALID Systems helps financial institutions prevent fraud in real time across teller, ATM and mobile channels, guaranteeing over $6 billion in immediately available funds each month across more than 425 million unique accounts.
After its legacy solution had reached its ceiling, VALID Systems rearchitected its fraud detection ML platform on Snowflake so that all features, training data, models and inference exist in one place, maintaining the same API contract with zero egress.
VALID’s models now optimize for the dollar value of the decisions they make, not just whether they got a row right or wrong. This shift in objective compounds performance. A small improvement targeting the highest-risk transactions outweighs a larger improvement spread evenly across all of them. Every tuning run is logged and fully auditable, so compliance teams get the documentation as a byproduct of the process instead of as an afterthought.
As a result of this new platform change, VALID achieved a 7%-10% drop in deposit loss rates and detected 15%-17% more bank fraud losses.

Real-time ML at banking scale is a solved problem on Snowflake.
Michael Ring
CTO/CIO, VALID Systems
Another customer that has modernized fraud detection at scale is Neon, which is one of Brazil's fastest-growing digital financial institutions serving over 27 million customers with payments and credit products. Every login, card payment, transfer and loan request first passes through Viper, Neon's in-house fraud engine. Viper needs fresh behavioral features, such as transaction counts over windows from minutes to months, to make a decision in real time.
Neon's previous feature store vendor Tecton was being discontinued, which gave the team a hard deadline. Neon evaluated several providers and picked Snowflake for four reasons: low latency, fresh streaming and real-time features, the same governance across online and offline features, a Pythonic developer experience, and more control with costs visible in one place.
In three months, the team rebuilt almost 300 features across eight fraud workflows on Snowflake Feature Store. As a result, Neon cut P99 feature latency from 140 ms to 72 ms, making it almost two times faster in Snowflake. Viper's service availability rose from 99.7% to 99.9% increasing the Viper’s anti-fraud coverage.
Machine learning models are at the center of our growth strategy, and that is only possible with a feature store that can grow at scale. With Snowflake Feature Store, our P99 latency dropped from around 140 milliseconds to around 72 milliseconds — almost two times faster — and our fraud engine's availability went from 99.7% to 99.9%.
Thiago Bianchi, Ph.D.
Senior Staff Software & Machine Learning Engineer, Neon
The technical blueprint for modern fraud detection
With Snowflake ML, customers such as VALID Systems and Neon are able to build robust fraud detection platforms that scale to the modern business demands because we provide the following benefits out of the box:
Low-latency predictions: Features served in under 10 ms with the Online Feature Store and models in under 100 ms from Snowflake Model Registry.
Integrated monitoring: The capacity to easily monitor, explain and receive alerts on performance and accuracy over time with built-in MLOps.
Security and governance: Unified data, features and models on a single platform, eliminating risks from egress of sensitive customer data.
Online ML capabilities, including online feature serving and model serving, are at the core of real-time fraud detection workflows. Today, we are thrilled to share that Snowflake’s Online Feature Store is now generally available, joining model serving for any production use case. Built on Snowflake Postgres, our Online Feature Store serves fresh, latency-sensitive ML signals — risk scores, activity patterns and behavioral features — to models at prediction time. These workloads require thousands of predictions per second, each needing features returned in milliseconds. The Online Feature Store is integrated directly with online model serving to easily generate low-latency fraud predictions.
Once the features are computed, the model is ready to be served in real time. For model serving, Snowflake deploys trained models as fully managed inference services on Snowpark Container Services (SPCS). Any model registered in the Snowflake Model Registry can be deployed with a single API call to a dedicated REST endpoint. The model service integrates directly with the Online Feature Store, and the service automatically fetches the latest features from the online store. This tight coupling between feature retrieval and model execution means a comprehensive fraud scoring decision — from feature lookup to prediction — happens in a single network round trip, minimizing network latency and external data movement.
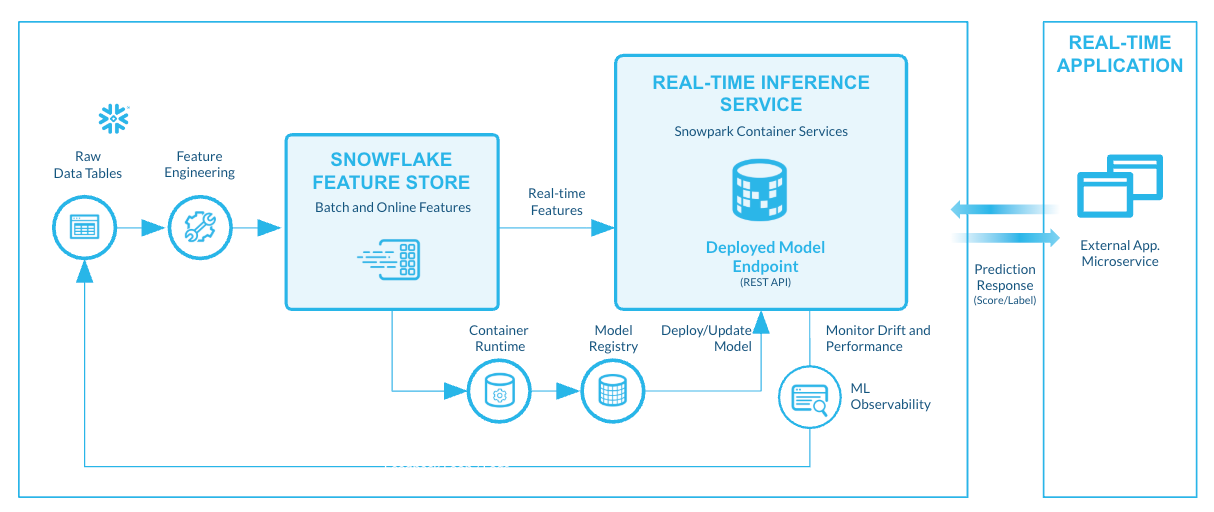
Figure 1: The Online Feature Store is directly integrated with online model serving, allowing customers to look up features directly from model inference requests.
Together, the Online Feature Store and online model serving, paired with our integrated ML platform, deliver the technical foundation needed to solve the industry’s biggest fraud detection hurdles. Let’s dive into how Snowflake ML addresses the most business-critical needs for financial institutions.
From event to decision in milliseconds
Catching fraud means the model must see the freshest possible signals — not features computed in last night's batch run but signals that reflect what happened seconds ago. Snowflake's online ML platform is built around streaming features that keep fraud decisions based on fresh signals as events unfold.
At the core are stream feature views, which ingest events such as transactions, logins and device signals in real time through a REST ingestion API and serve updated features with end-to-end freshness in under 200ms p50. Behind the scenes, events are written synchronously to a managed Postgres serving layer for low-latency reads. As events arrive, the Online Feature Store continuously computes time-windowed aggregations such as "total spend in the last 48 hours" or "number of transactions in the last hour," maintaining running totals rather than periodically rescanning raw event history. This means the fraud model always sees behavioral signals that reflect the very latest activity, not a stale snapshot.
For features that depend on the current request, such as the transaction amount or device fingerprint, real-time feature views compute derived values on the fly at query time. A Python function runs at inference time, combining per-request inputs with precomputed features from upstream feature views before they reach the model. For example, a fraud model can compare the current transaction amount (at request time) to a customer's rolling average spend (continuously maintained by the stream feature view) to flag anomalies the moment they occur.
Integrated monitoring and experimentation
Fraud models degrade as adversaries adapt. Snowflake's MLOps is natively integrated with our feature store and model registry to easily monitor, explain and receive alerts on performance and accuracy over time. Gateway monitoring, model observability and online feature serving dashboards are all accessible from Snowsight, giving teams a single pane of glass across the entire ML lifecycle. Model monitors continuously measure drift, performance and prediction volume. When ground truth labels arrive, Snowflake joins them to inference logs automatically, computing accuracy, precision and recall without additional pipeline work.
For experimentation, Snowflake’s gateway monitoring supports A/B testing and shadow testing, letting you split or mirror live traffic between model versions and compare accuracy, latency and error rates before promoting a challenger. The Online Serving tab provides real-time visibility into feature store health. All of this is secured and governed by default because it occurs on the same platform as your data.
Unified security and governance
Fraud detection systems handle some of the most sensitive data an organization holds: account numbers, transaction histories and personally identifiable information. A common risk with legacy architectures is that inference calls send this data to an external platform, creating governance gaps that regulated financial institutions cannot tolerate.
In Snowflake, the entire ML lifecycle — from feature engineering through model training, serving and monitoring — runs on the same platform where the data already lives. Sensitive data is secured and processed within Snowflake's security perimeter. Models are schema-level objects with full role-based access control: You can grant fine-grained privileges so data scientists can iterate in development, while production roles control what gets promoted. ML Lineage automatically traces how data flows from source tables through feature views and data sets and into registered models and services, giving compliance teams end-to-end provenance. And because all of this is governed by Snowflake's unified security model, the same network policies, encryption and audit logging that protect your data also protect your ML workflows.
Agentic fraud detection workflows
At Snowflake, we are also committed to helping teams accelerate development with agentic ML workflows from Snowflake CoCo. Data science teams can rapidly build fully functional, high-quality ML pipelines by using CoCo to agentically plan, reason and select the optimal technique for each step across development and inference. Instead of spending cycles on navigating documentation, debugging errors or stitching together APIs, you can focus on applying your fraud domain expertise and intuition to refine models and drive insights.
We support full agentic workflows for fraud detection use cases. Follow along in this quickstart to build a fraud detection model with CoCo using only natural language prompts.
Performance
Our benchmarks show that both online feature serving and online model serving outperform competitors for the latency and cost that enterprises need for fraud detection. Snowflake’s Online Feature Store serves features in real time at 2.5x lower latency and 7x higher QPS than Databricks, and real-time model inference in Snowflake is 2x-5x faster and up to 3x cheaper in Snowflake than in Sagemaker and Databricks.
For the Snowflake Feature Store, we are able to deliver consistently low-latency serving through a Postgres-backed engine, typically under 10 ms at P50 for low latency reads – paired with a dedicated streaming transformation engine that enables end-to-end freshness typically under 200 ms at P50. With native connection pooling and per-schema single-tenant isolation on SPCS, the stateless REST endpoint sustains consistent low latency even through traffic spikes, load tested beyond 40,000 QPS.
For inference, we also deliver faster and cheaper model inference by decoupling CPU-heavy serving tasks — such as request handling, serialization and batching — from GPU-bound model execution, allowing each layer to scale independently. Dynamic batching processes requests instantly at low traffic while automatically combining them under load to maximize GPU parallelism, and request pipelining keeps GPUs continuously fed by staging the next batch before the current one finishes — eliminating idle gaps and driving higher throughput per GPU.
Getting started
To get started building real-time fraud detection workflows in Snowflake, check out the following resources:
Comprehensive fraud detection guided quickstart
Guided quickstart to try out agentic ML for fraud detection

