Flakes of Weight-Space Programming: fixing a neural network by having an LLM edit its weights on Snowflake
If you want to own your company's intelligence, you need to be able to change how an open model behaves. Post-training is one way to do that, but for many organizations this can be a large hurdle in both complexity and cost.
Weight-space programming is an early look at an alternative way to change model behavior. The idea is simple. Instead of training, you ask an LLM to edit a neural network's weights directly. It's an exciting emergent behavior of LLMs, and a glimpse of what might be possible as LLMs continue to scale.
What is weight space programming
In Sparks of Weight-Space Programming, Takehi, Teoh, Zhang, and Khattab (MIT CSAIL) define it this way:
In Weight-Space Programming, a general-purpose LLM reads and writes a network's weights directly (i.e., not through an optimizer, and in particular not with gradient descent) around some natural language spec, sometimes even with no environment feedback at all.
A network's weights are the numbers in its matrices and bias vectors. They decide what the network outputs for a given input. Normally an optimizer sets them from data. Here, an LLM reads them as text and replies with new values.
This is different from fine-tuning a subset of layers. Freezing layers or adding LoRA adapters still uses data, a loss, and gradient descent to pick the new numbers. In weight-space programming the LLM picks both which weights change and what they change to.
What surprised me is that the LLM reasons about the weights themselves. It doesn't post-train, compute a loss, or follow gradients. It reads the numbers, works out what parts of the network compute, and writes new values from that understanding. In this blog I reproduced a simple update to a relatively small neural network, but it is easy to imagine where this can go in the future.
The experiment
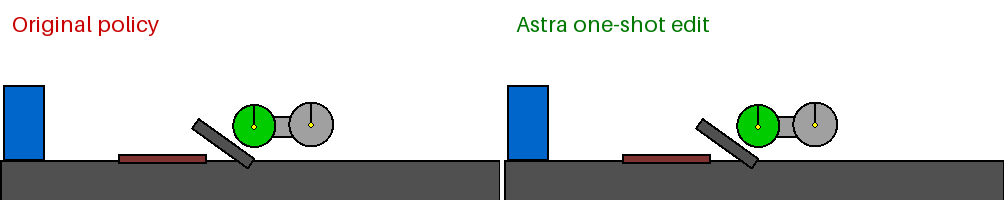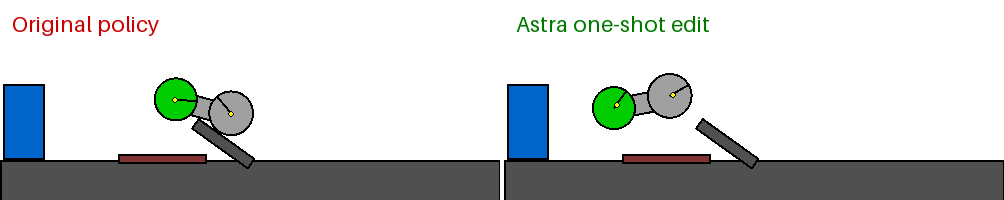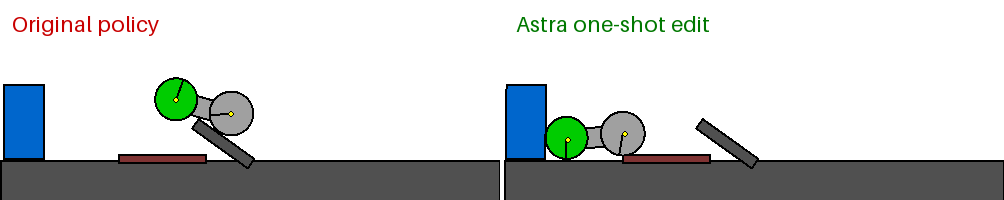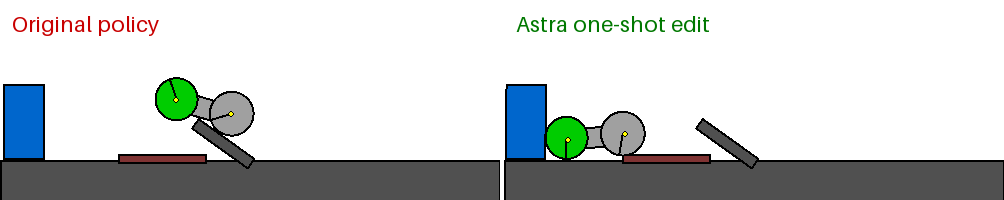
The paper's Experiment 4 uses a level from Kinetix, a 2-D physics environment. A small car has to back up to get a run-up, then drive forward fast enough to jump a red strip and touch a blue box. Touching the red strip ends the episode as a failure.
The policy is the official Kinetix actor network:
| Layer | Shape | Weights |
|---|---|---|
| Input to first hidden layer (ReLU) | 679 → 128 | 87,040 |
| Five hidden layers (tanh) | 128 → 128, ×5 | 82,560 |
| Output (16 action logits) | 128 → 16 | 2,064 |
| Total | 171,664 |
The 679 inputs describe each body's position, velocity, and shape, plus the joints. The 16 outputs are logits for the motor and thruster actions. The authors trained it with PPO for 1 billion steps, and it converged to driving straight at the ramp and stalling.
The paper reports that GPT-6 Astra wrote a fix in one reply, given the weights, a scene description, and one recorded episode. The car succeeded in all 1,024 test episodes, and 3.5% of the weights changed.
Weight space programming in Snowflake
I reproduced this using the Cortex REST API. The authors' prompt is 352,000 prompt tokens containing the task, the scene, one recorded episode, and all 171,664 initial weight values.
import requests

payload = {
    "model": "openai-gpt-6-astra",
    "messages": [
        {"role": "system", "content": "Answer the user's request."},
        {"role": "user", "content": prompt_text},
    ],
    "reasoning_effort": "high",
    "max_completion_tokens": 65536,
    "stream": False,
}
response = requests.post(
    f"{account_url}/api/v2/cortex/v1/chat/completions",
    headers={"Authorization": f"Bearer {pat}", "Content-Type": "application/json"},
    json=payload,
    timeout=(30, 1200),
    allow_redirects=False,
)
reply = response.json()["choices"][0]["message"]["content"]
Astra replies with its reasoning and a list of assignments such as actor_head.b[0] = -100. A small parser applies them to the original weights.
The edits arrive in a fenced edits block at the end of the reply. These are the first lines of Astra's successful edit:
embed.W[:, 6:9] = 0
embed.W[:, 13] = 0
embed.b[6:9] = [0, 10, 0]
embed.b[13] = 3
embed.W[52, 6] = 1
Each line names a tensor, an index or half-open range, an operator (=, *=, +=, or -=), and a number or list of numbers. The parser applies them in order to a copy of the original weights. It skips any line it can't read and records why, and it rejects edits that produce non-finite values. The full parser is in car_policy.py.
Experiment results
I scored every policy on the same 1,024 episodes. Each episode ends in one of three ways:
- Success: the car's green wheel touches the blue box.
- Red collision: the car touches the red strip. The episode ends immediately as a failure.
- Timeout: 256 steps pass without either.
| Policy | Success | Red collision | Timeout |
|---|---|---|---|
| Original PPO policy | 0 | 0 | 1,024 |
| Astra, paper's prompt | 0 | 39 | 985 |
| Authors' published edit | 1,024 | 0 | 0 |
| Astra, with one added instruction | 1,024 | 0 | 0 |
With the paper's prompt alone, Astra returned two edits, both to the output biases: actor_head.b[0] = -100 and actor_head.b[1] = 8.052. That shifted the policy toward one motor action everywhere. The car either still stalled or backed into the red strip.
The car needs different behavior in different states: reverse first, then drive forward once there's enough runway. The second attempt added one instruction in front of the paper's prompt and left the rest unchanged:
Consider whether the repair requires different actions in different physical states rather than a constant action preference. Define the conditions using the available observations, map those conditions through the network's activations, and check the signs and thresholds of your proposed numerical edits. You must determine the weights yourself.
Cortex Code (CoCo) examined that failure mode and wrote the instruction. It compared Astra's constant bias shift with the paper's description of the authors' fix, which adds a path that reads the car's position and speed.
What Astra's state-dependent edit changed
With the added instruction, Astra changed 7,326 of 171,664 weights (4.3%) and the car succeeded in all 1,024 episodes, taking 91.9 steps on average. In comparison, the authors' edit took 73 steps and changed 6,073 weights.
Astra's reply starts by diagnosing the failure from the weights and the recorded episode:
The trace shows the resulting failure: it approaches the ramp correctly, but then repeatedly chooses off or positive drive while stalled astride the crest. Reverse is effectively absent.
It then defines conditions on the body's horizontal position and velocity and the right wheel's position. It routes those through four embedding units so the policy reverses first and drives forward once it has a run-up.
LLMs are probabilistic predictors, so I'm not surprised the paper's prompt didn't work on the first try and adding additional instruction the car policy should be stateful is a reasonable hint. Astra still had to work out which inputs describe that state, route them through the network, and write every number itself.
Running it yourself
The code and results are in Snowflake-Labs/weight-space-programming so you can try weight-space-programming yourself in Snowflake.
This content is provided as is, and is not maintained on an ongoing basis. It may be out of date with current Snowflake instances
