Ebook
10x Faster Incident Troubleshooting: The AI SRE Playbook
Learn how AI-driven observability accelerates incident investigation, improves root cause analysis, and dramatically reduces MTTR.
Use Case
Monitor your infrastructure across cloud, Kubernetes, containers, serverless and applications in real time. Pre-built apps model your stack the moment you connect, so you can find and resolve issues before they reach your users.
Overview
Modern infrastructure is dynamic and ephemeral, so failures are hard to catch and their root cause is even harder to trace. Unify your telemetry to detect, monitor and address issues with Observe by Snowflake.

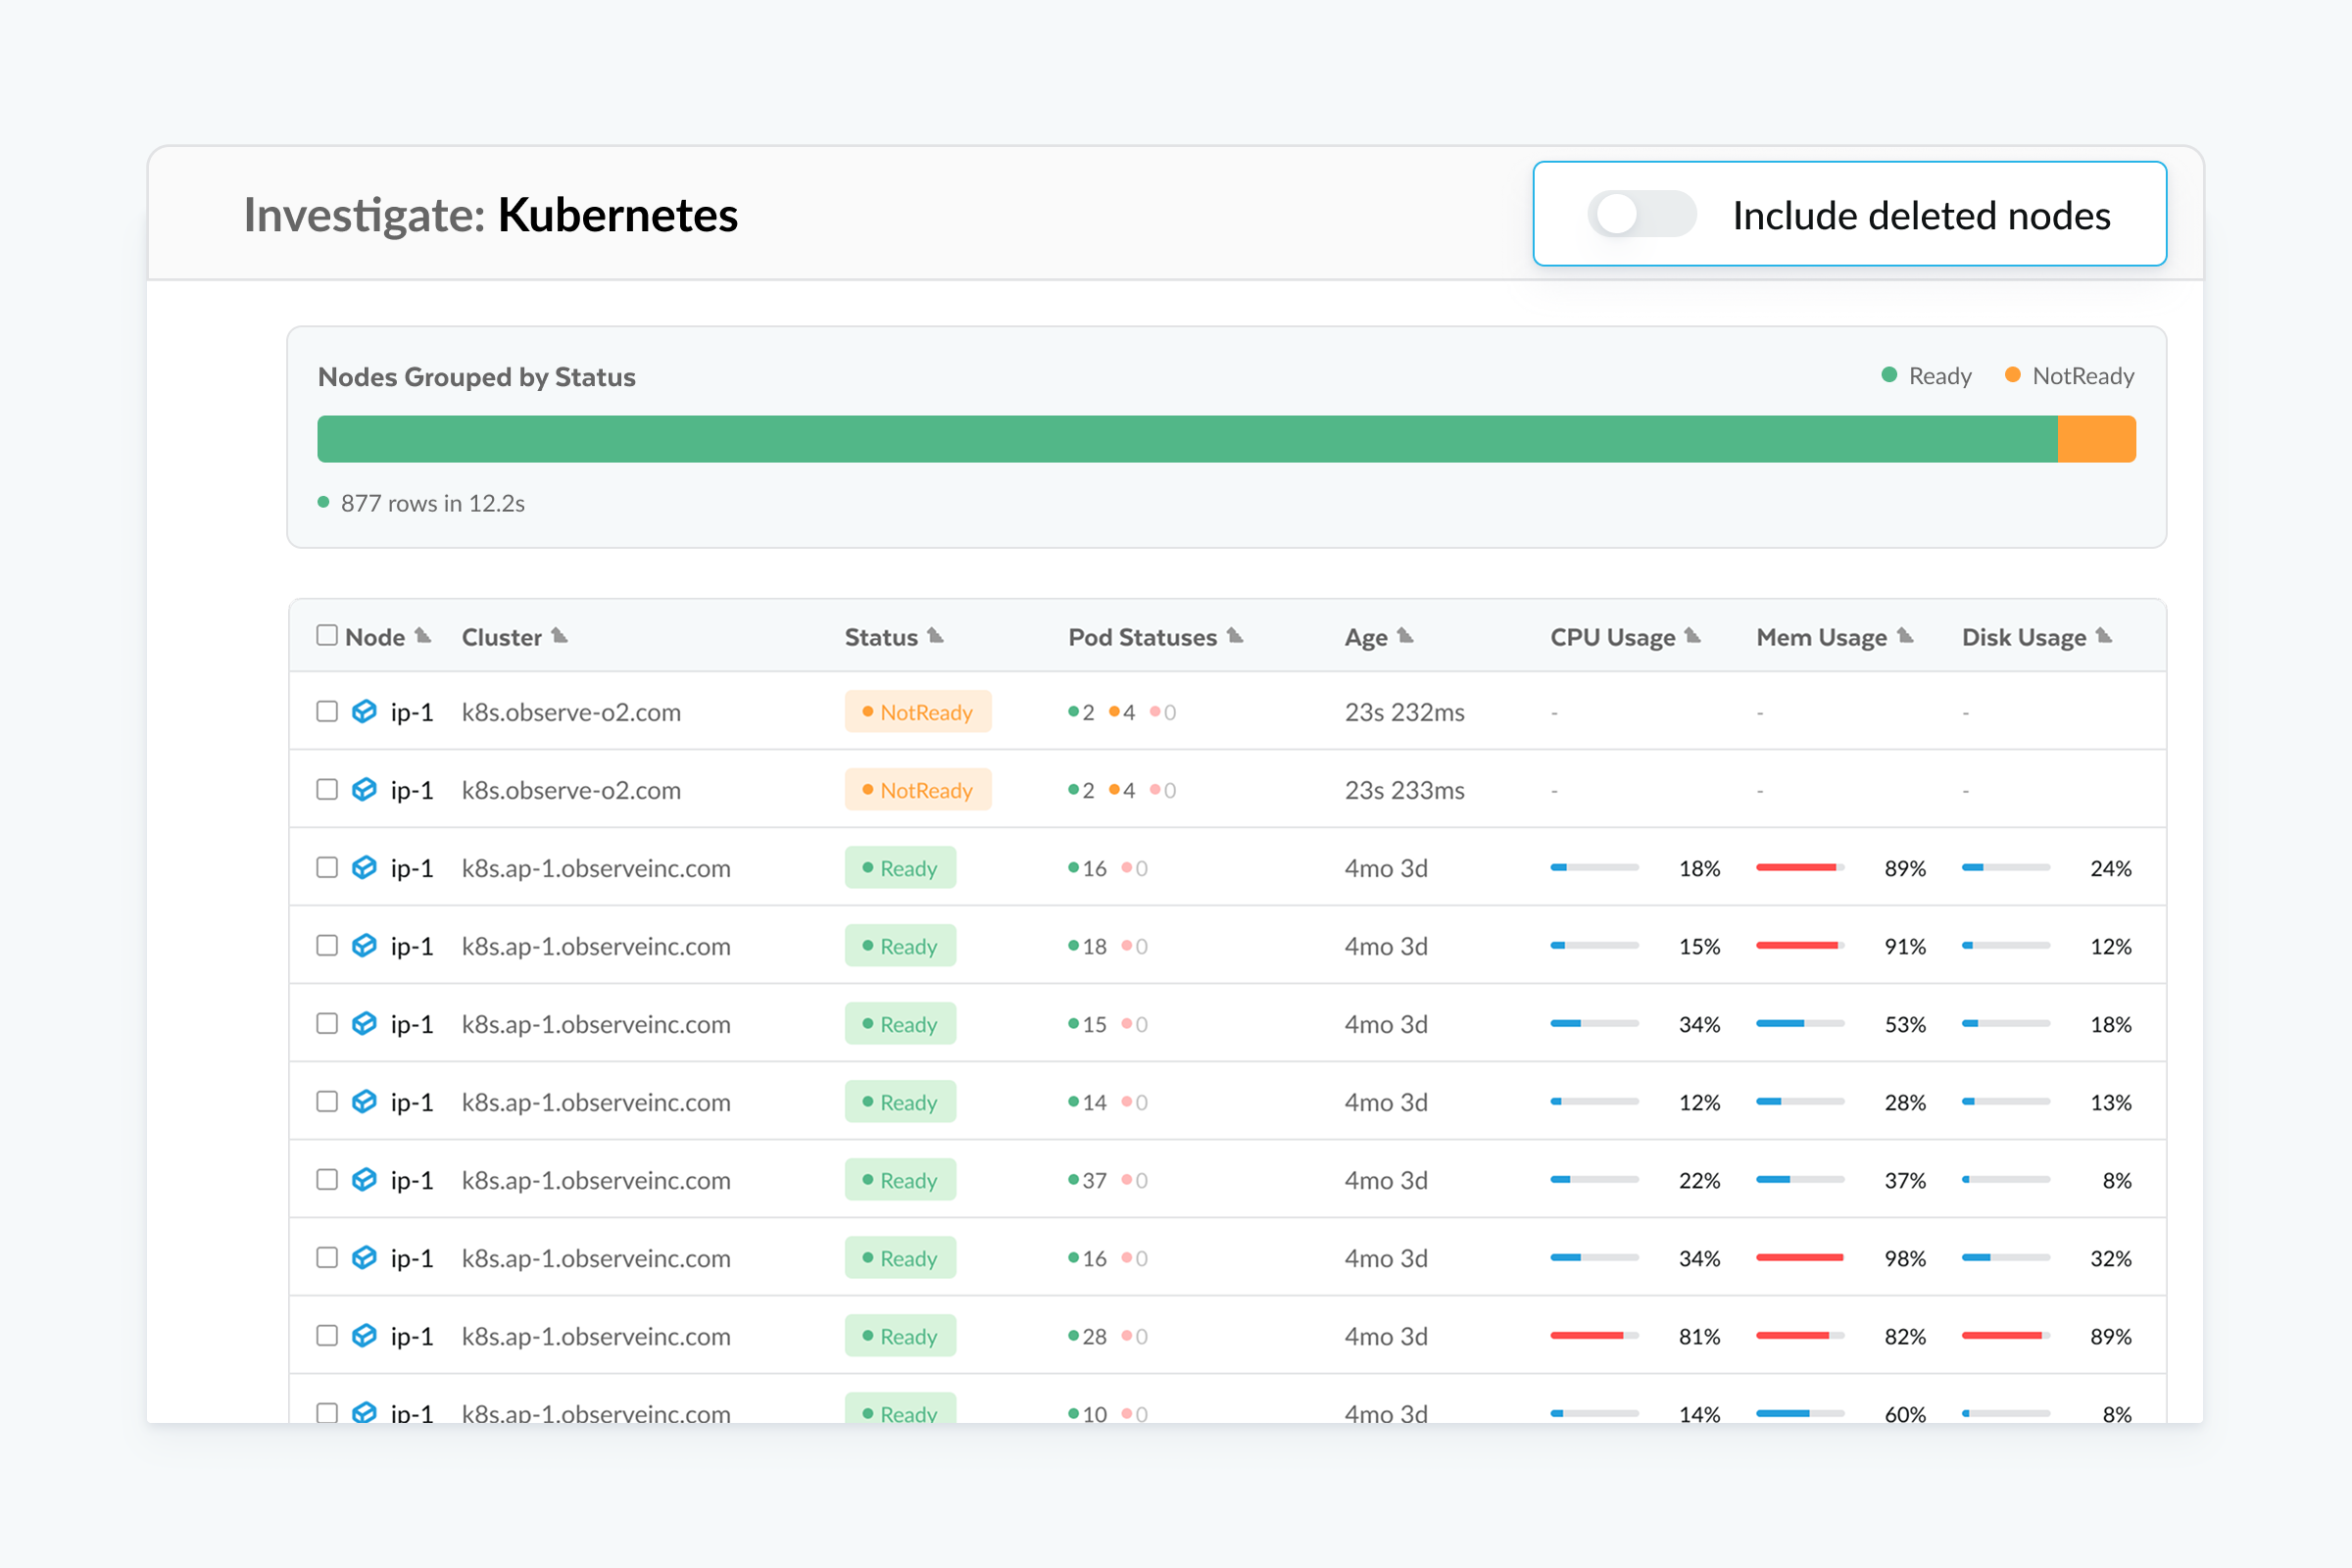
Bring cloud, Kubernetes, containers and serverless into one real-time view with pre-built apps and dashboards that surface service health, availability and performance.

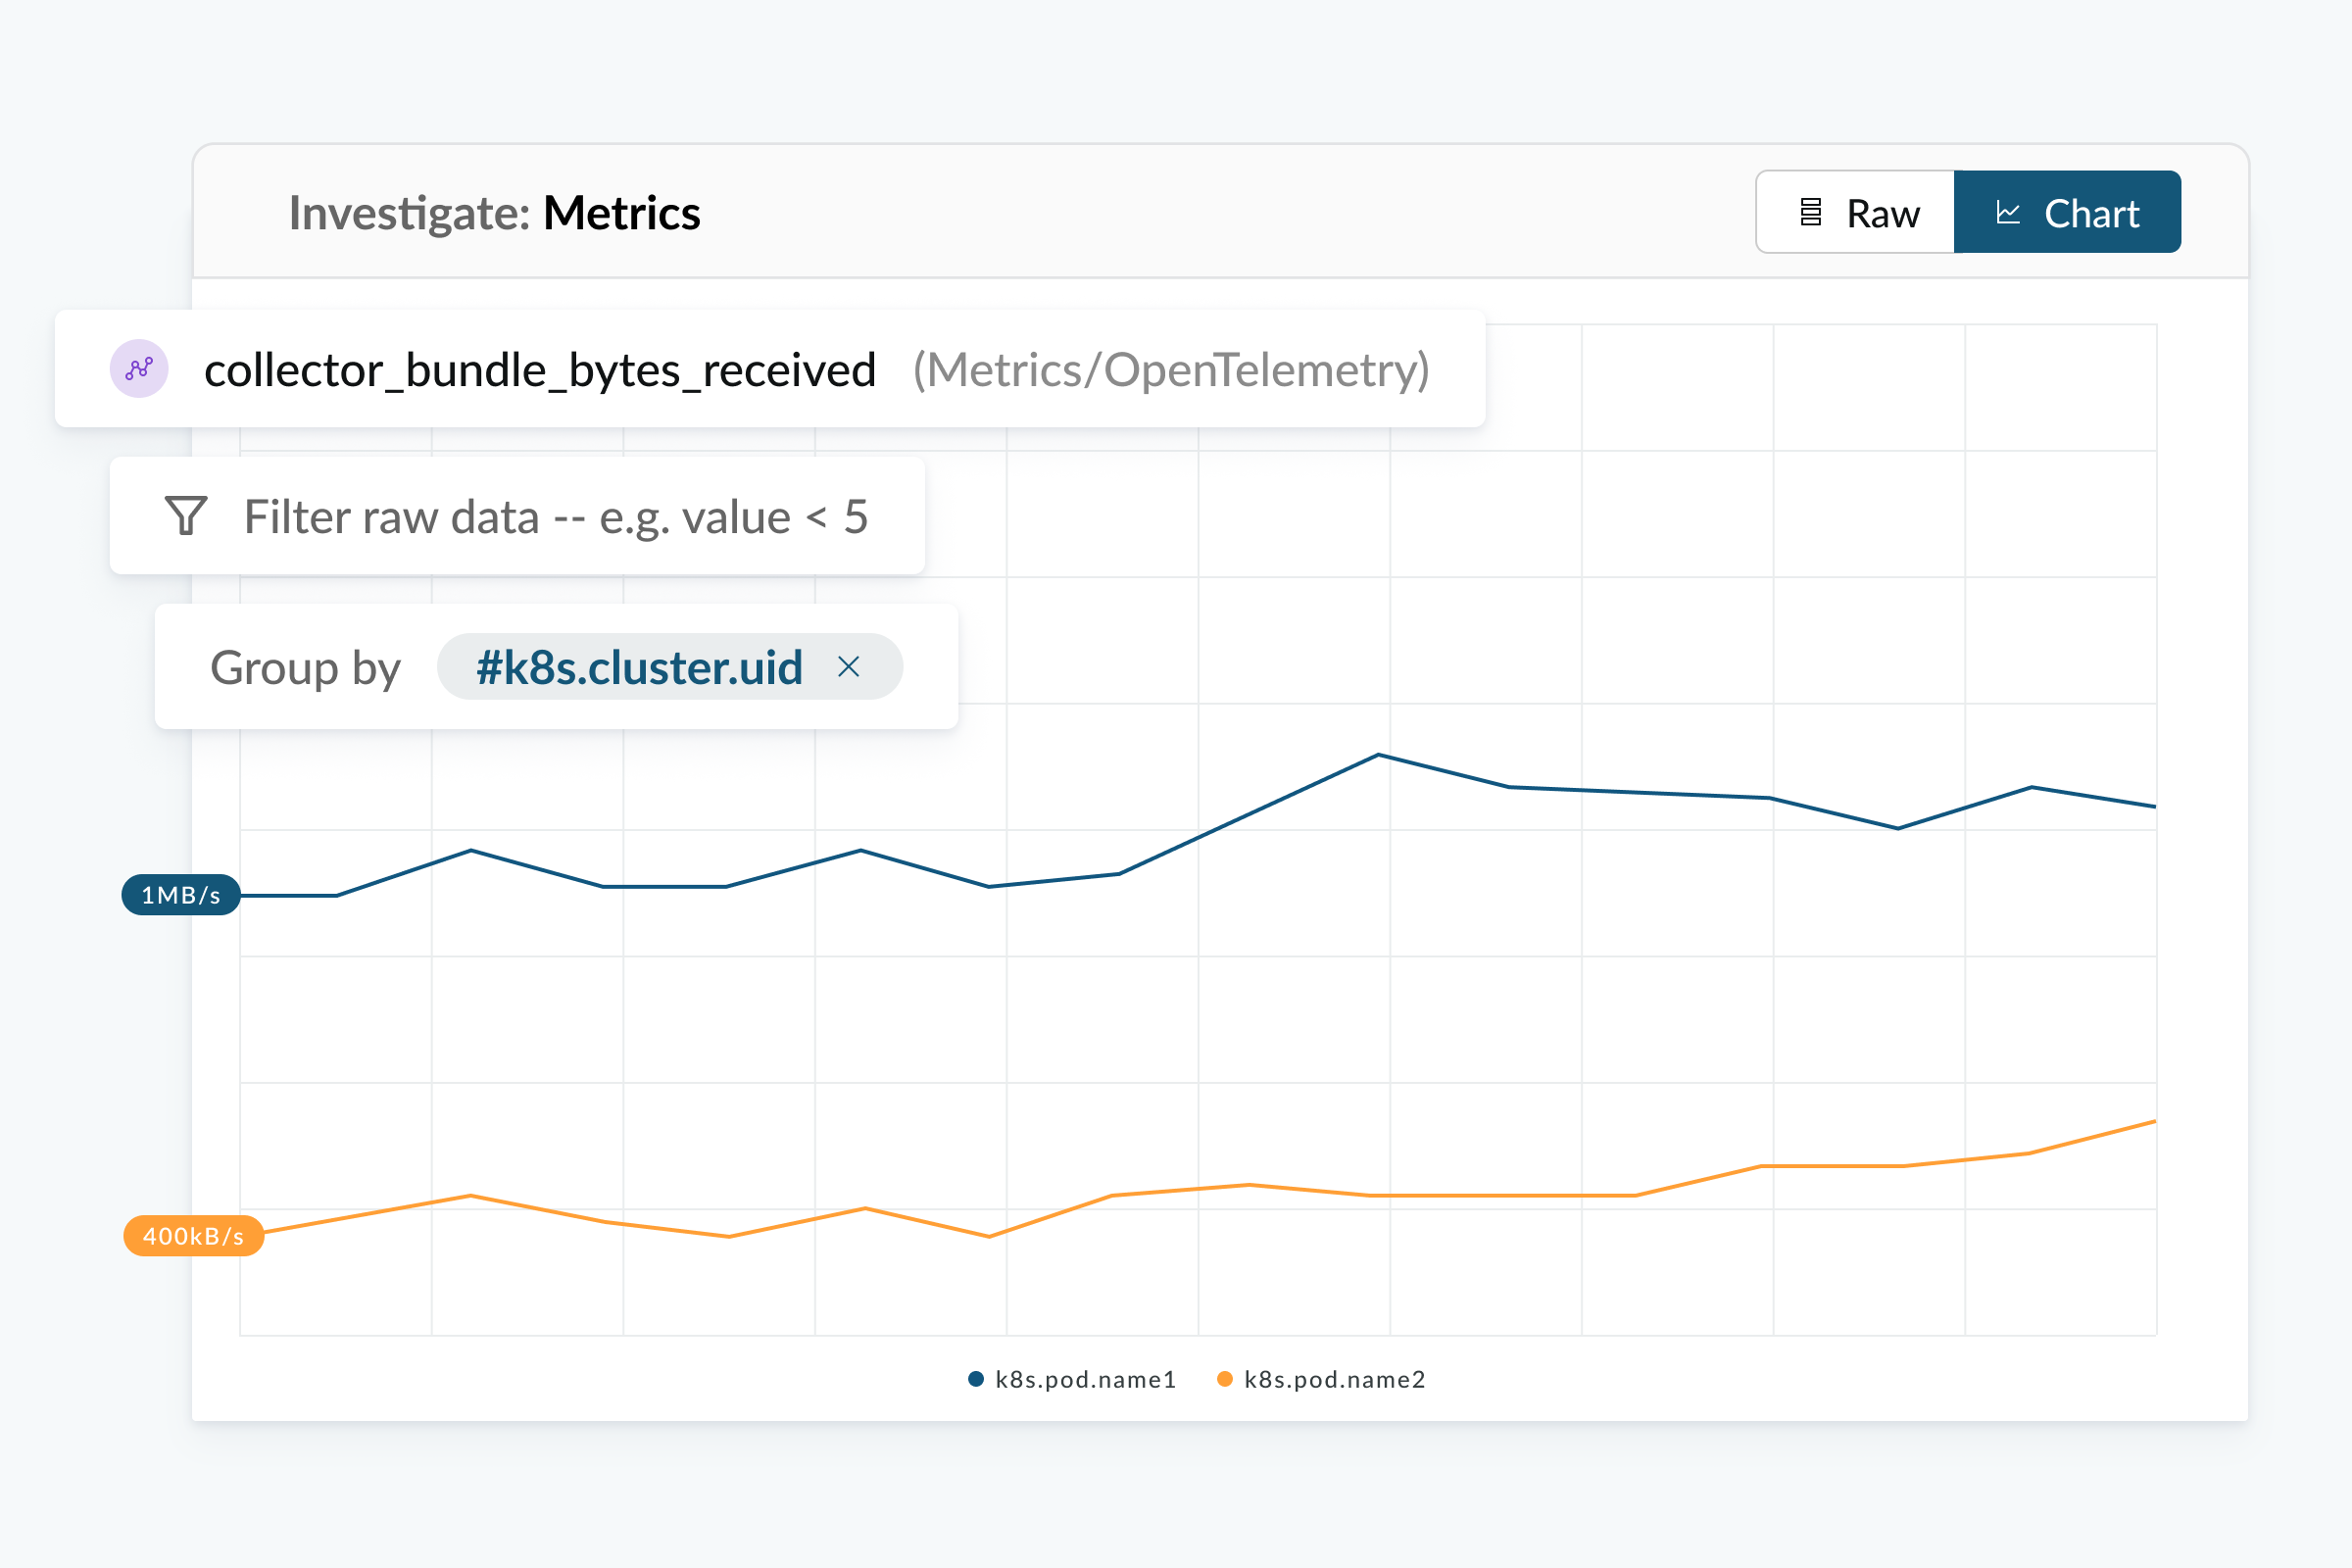
Every pod, container and host is a new dimension. Snowflake's architecture changes the economics: keep all your high-cardinality data instead of dropping it to cut cost.

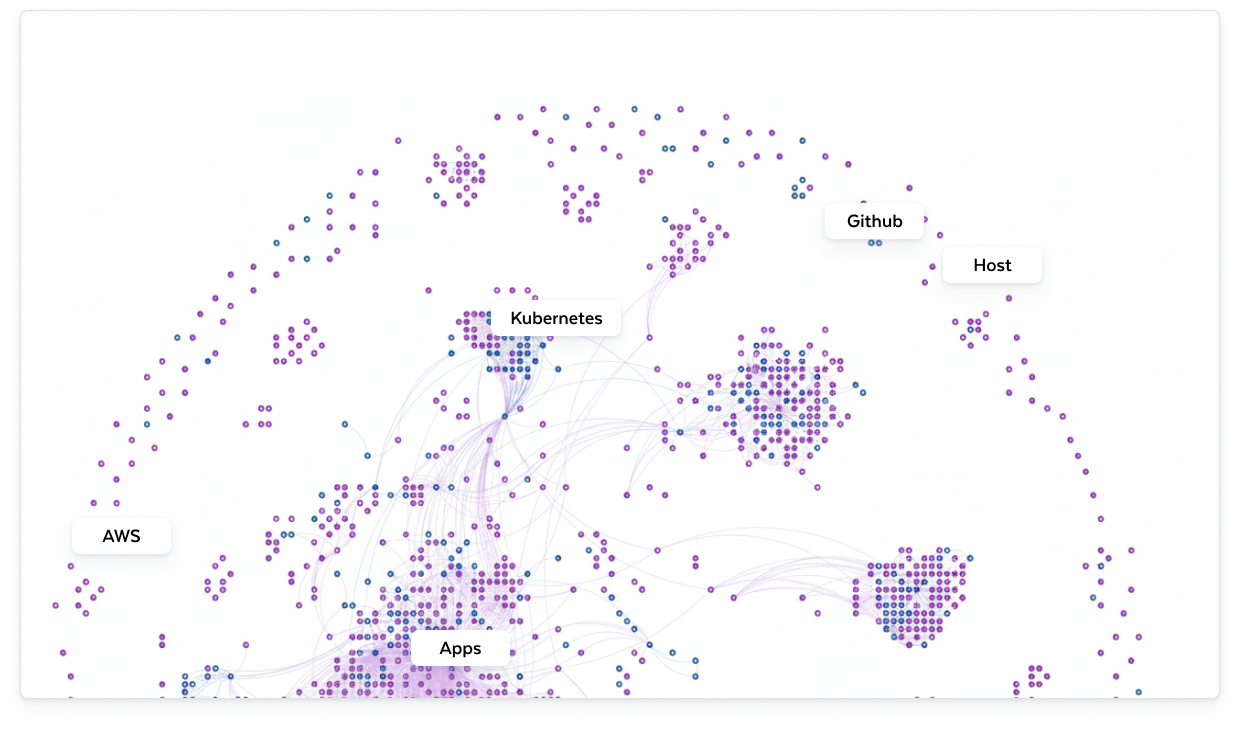
Know what happened with in-context alerts and direct pivots to the logs. Automatically map cloud interdependencies and move from anomaly to root cause in fewer steps.
Benefits
Every stack and scale
High cardinality analytics
Context
Prometheus-ready
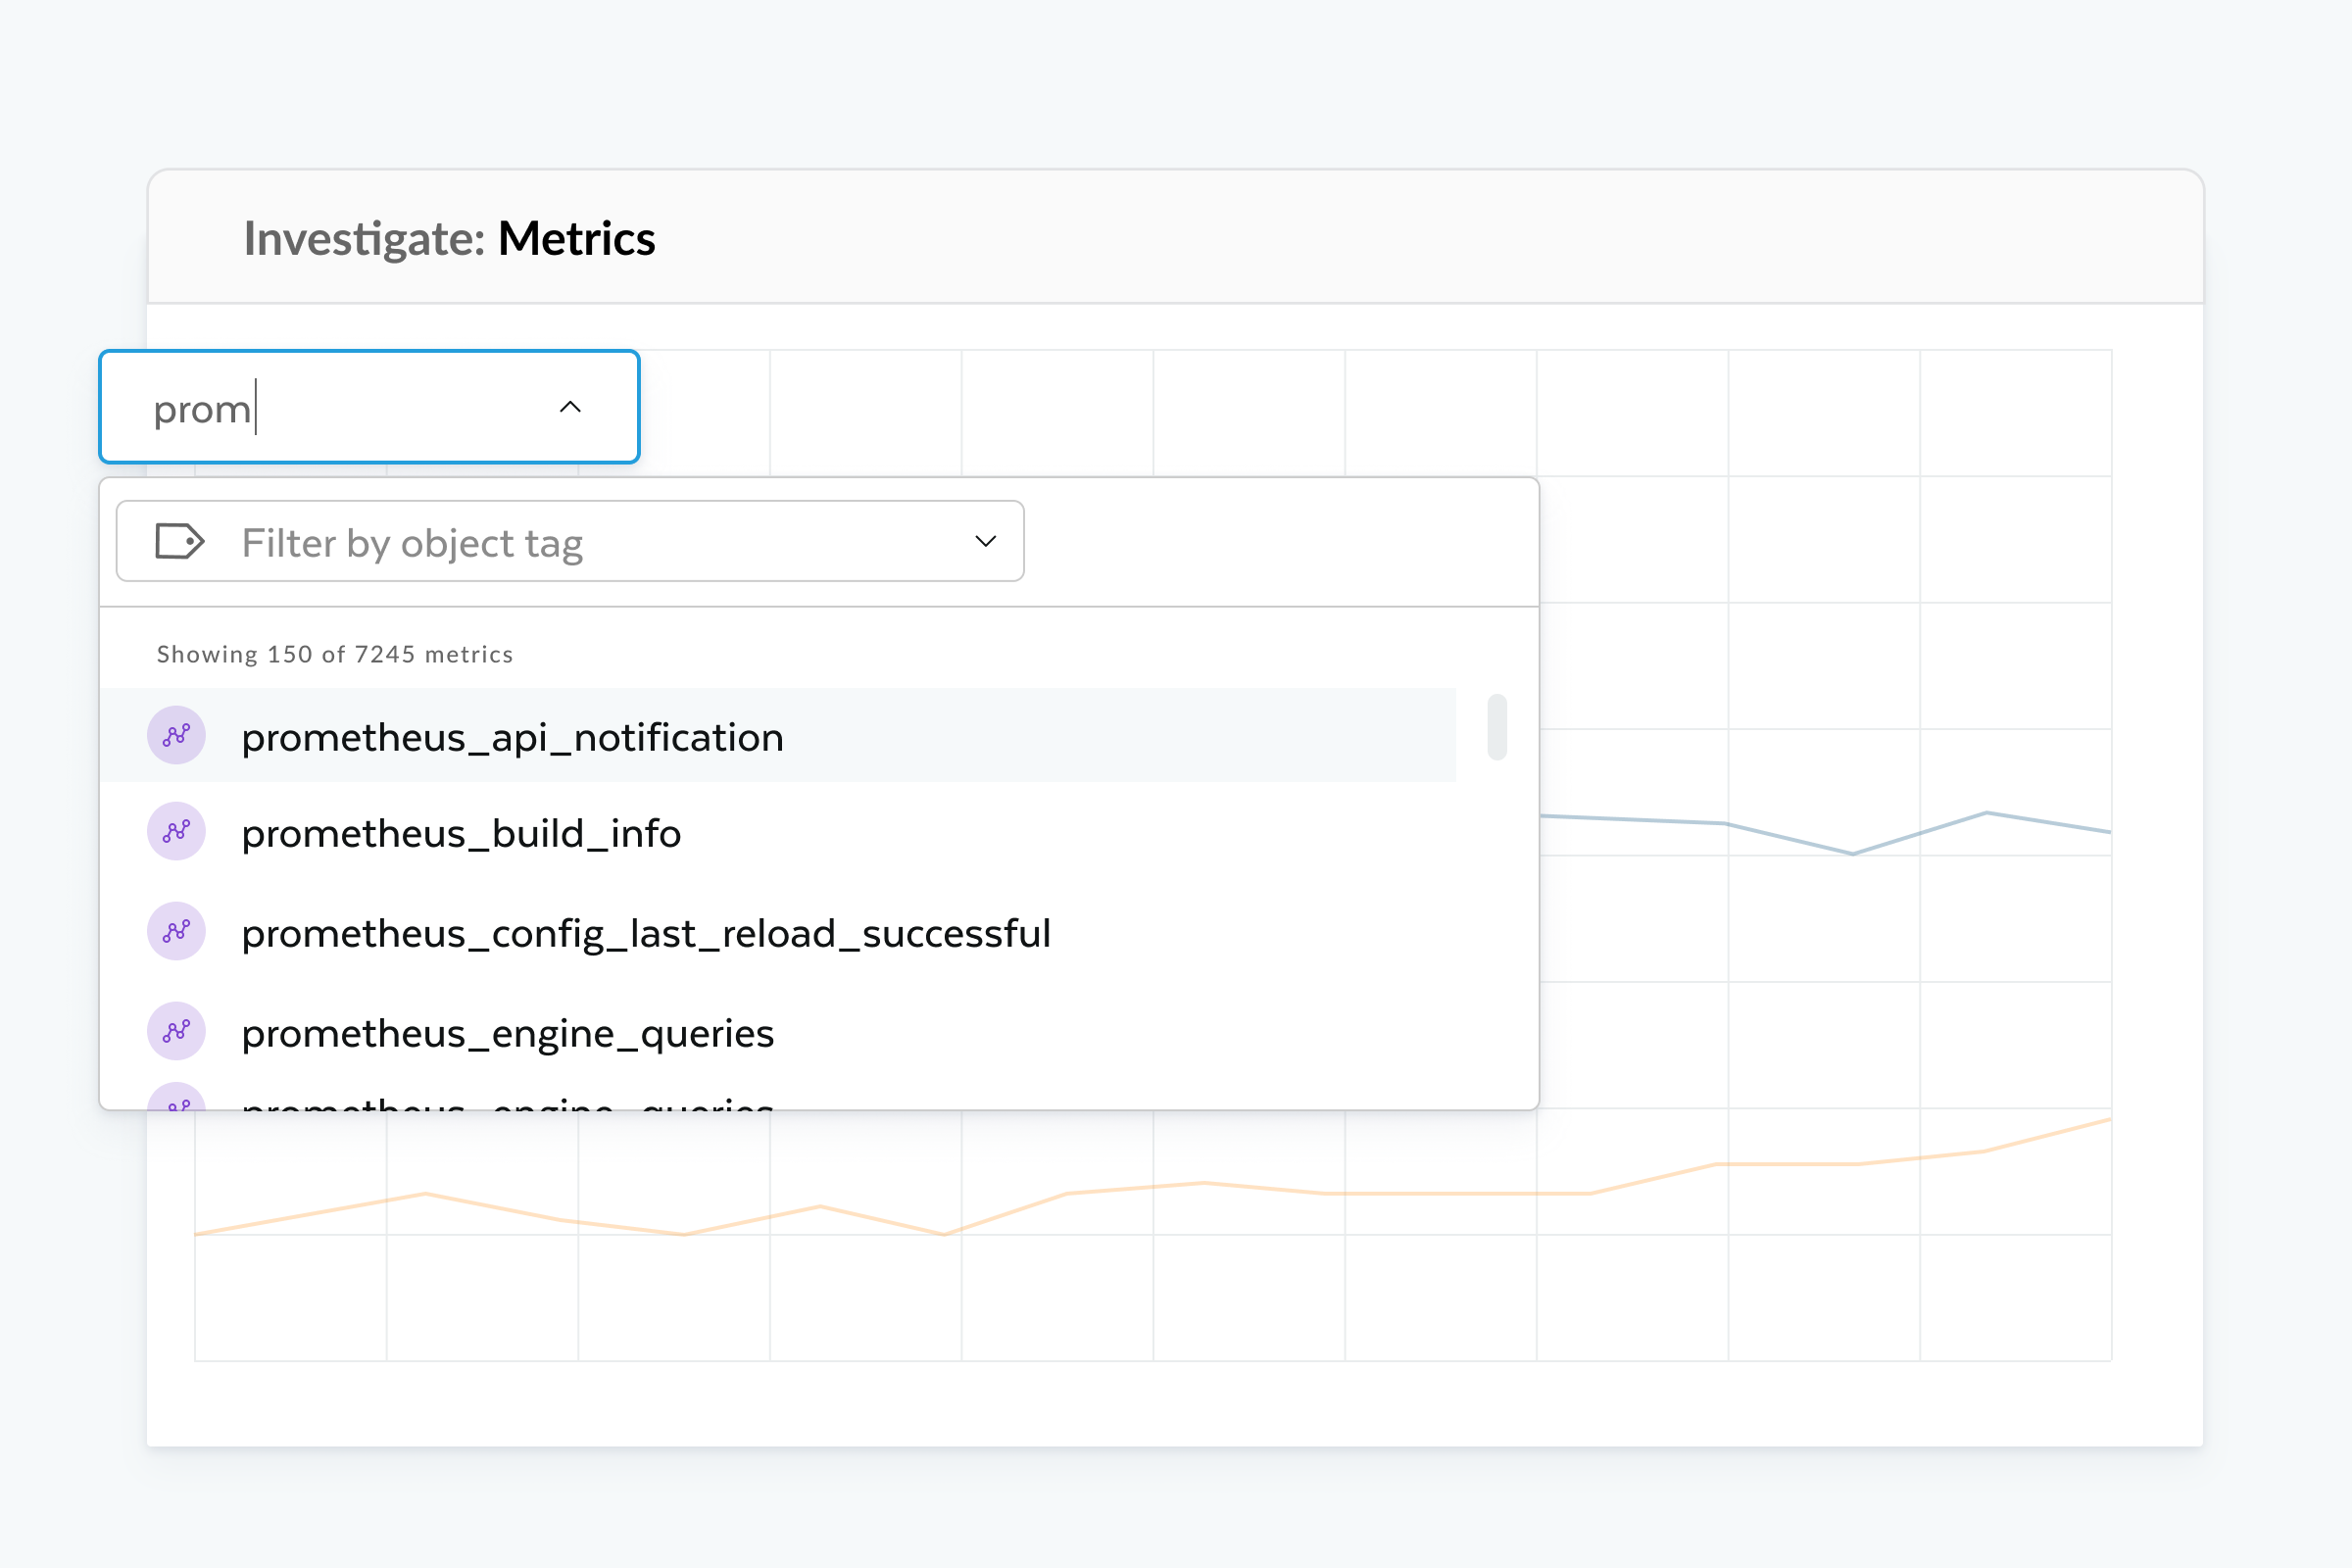
Stream Prometheus metrics into Observe with native remote-write support.
Aggregate metrics from multiple Prometheus instances for centralized analysis across environments.
Preserve existing instrumentation while expanding visibility across teams, services and infrastructure.

Topgolf Eliminates Infrastructure Monitoring Silos with Observe by Snowflake
Topgolf replaced siloed infrastructure monitoring tools with Observe by Snowflake, cutting costs and giving engineers one platform to correlate infrastructure, application and business data across 50+ locations globally.
Resources
Get Started
Performance at scale
Faster troubleshooting
Lower cost with an open data lake

Observe AI SRE
Get quick answers to your AI SRE questions and learn how Observe by Snowflake helps you troubleshoot faster at scale.
An AI SRE is an AI agent built for incident investigation. It correlates logs, metrics and traces across your environment, surfaces what triggered it, and suggests remediation steps so engineering teams can resolve incidents faster. Observe's AI SRE grounds its analysis in the Observability Context Graph, which maps the relationships across your services, infrastructure, logs, metrics and traces. Observe’s AI SRE primarily serves SREs and on-call engineers and is easily accessible through a chat interface in Observe.
Observe also brings AI assistance into the workflows your broader engineering team already uses, including log search, trace analysis and other surfaces across the product, so teams can benefit from AI assistance without adopting a new interface.
Modern engineering teams generate more telemetry than any team can manually synthesize, and the volume only grows with microservices, AI-generated code, and agentic workflows. Meanwhile, investigation remains the dominant contributor to MTTR. Observe's AI SRE closes that gap. Rather than pulling context from multiple tools and running queries across fragmented systems, engineers ask a question and the AI SRE correlates logs, metrics and traces across the full environment, drawing on the Observability Context Graph to understand service dependencies, recent deployments, and business impact–and returns findings with recommended actions. The result is faster resolution that's accessible across the whole team.
SREs and infrastructure engineers are the primary users, but AI SRE extends investigation capabilities across the team. Developers can troubleshoot production issues directly from their IDE via the Observe MCP Server. Support engineers can investigate incidents without needing deep system expertise. Engineering leaders can reduce dependency on a small number of senior experts and make faster resolution accessible to the entire team.
Most AI observability tools layer AI on top of fragmented, siloed data and pull from multiple systems with gaps and duplicates. Observe's AI SRE runs on a unified Telemetry Lakehouse Foundation where all telemetry is stored together and structured by an Observability Context Graph that maps entity relationships across your stack. The AI SRE has complete context, not a partial picture, which means fewer false positives and more actionable root cause analysis.
Observe's MCP Server lets engineers troubleshoot directly from AI coding agents like Cursor and Claude. An Observe CLI also provides programmatic, agent-driven access to observability context, including reusable workflows for common tasks like investigating incidents, tracing failures, or validating changes.