Build a Video Search App with TwelveLabs on Snowflake
Overview
In this guide you'll turn a folder of video files into an app that lets you:
- Search every video by typing a description or dropping in an image, across what's seen, heard, and said, and jump straight to the matching moment.
- Analyze any video with a plain-language prompt and get structured answers back with Pegasus 1.5.
The whole pipeline runs inside Snowflake. No video leaves your account, and every model call is a SQL function.
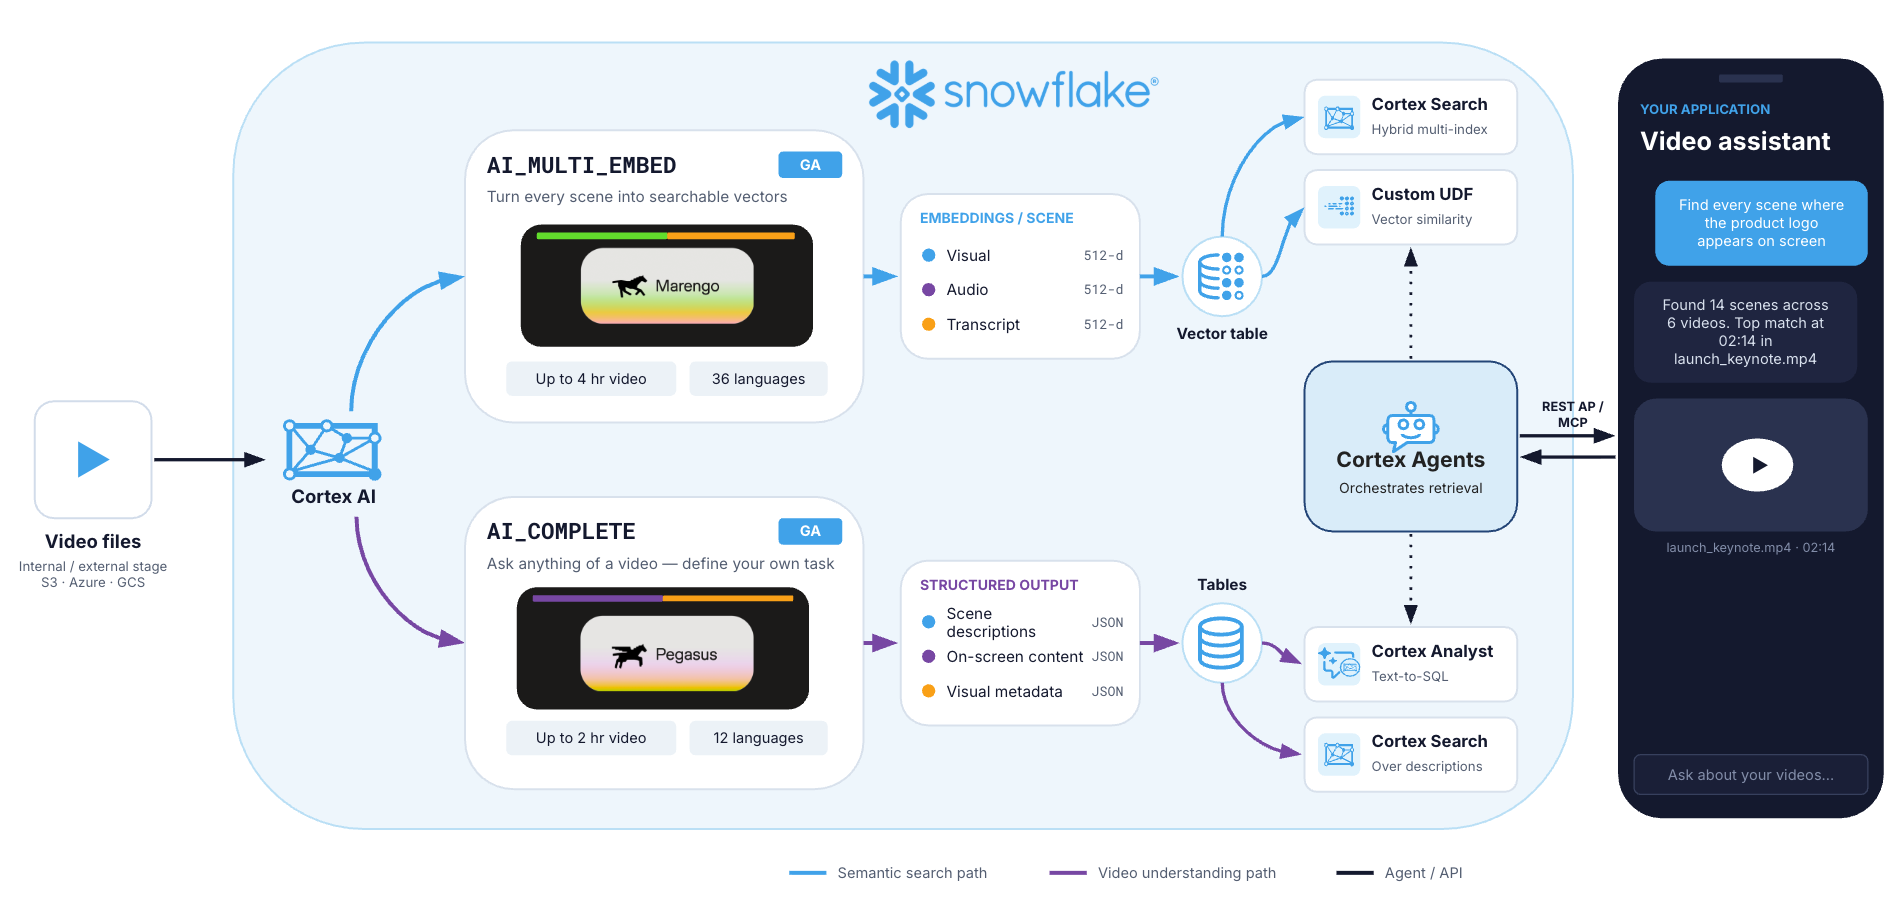
What You'll Build
| Step | What it does | Snowflake surface |
|---|---|---|
| 1. Stage | Point Snowflake at your videos | Stage + directory table |
| 2. Embed | Turn each video into time-stamped vectors | AI_MULTI_EMBED with Marengo 3.0 |
| 3. Index | Make visual, audio, and transcript vectors searchable | Cortex Search (multi-index) |
| 4. Search | Query one or all modalities at once | multi_index_query |
| 5. Analyze | Ask questions about a video | AI_COMPLETE with Pegasus 1.5 |
| 6. App | Put it all behind a UI | Snowflake App Runtime (Next.js) |
What You'll Learn
- How to embed video, text, and images into one shared vector space with
AI_MULTI_EMBED - How to build a Cortex Search service with multiple vector indexes, one per modality
- How to search them with
multi_index_query - How to ask questions about a video with
AI_COMPLETEand Pegasus 1.5 - How to deploy the app on Snowflake App Runtime
What You'll Need
- A Snowflake account in a region that supports
twelvelabs-marengo-embed-3-0, or with cross-region inference enabled. See AI_MULTI_EMBED regional availability. - A role with
SNOWFLAKE.CORTEX_USERand privileges to create a database, stage, and Cortex Search service - A few
.mp4files (a handful of short clips is enough to start) - Node.js 20+ and the Snowflake CLI to run and deploy the app
Stage Your Videos
Create a database, a schema, and a stage with a directory table. The directory table is what lets you list and reference files from SQL.
CREATE DATABASE IF NOT EXISTS TWELVE_LABS_DEMO;
CREATE SCHEMA IF NOT EXISTS TWELVE_LABS_DEMO.VIDEO_INTELLIGENCE;
USE SCHEMA TWELVE_LABS_DEMO.VIDEO_INTELLIGENCE;

CREATE STAGE IF NOT EXISTS VIDEO_STAGE
  DIRECTORY  = (ENABLE = TRUE)
  ENCRYPTION = (TYPE = 'SNOWFLAKE_SSE');
Upload your videos to the stage in Snowsight (Data » Add Data » Load files into a Stage), or from the CLI:
snow stage copy ./videos/*.mp4 @TWELVE_LABS_DEMO.VIDEO_INTELLIGENCE.VIDEO_STAGE
Then refresh the directory table:
ALTER STAGE VIDEO_STAGE REFRESH;
SELECT RELATIVE_PATH, SIZE FROM DIRECTORY(@VIDEO_STAGE);
aside positive Already have video in S3, GCS, or Azure? Create an external stage on a storage integration instead. The rest of this guide works the same with either kind of stage.
We also need a small internal stage where the app uploads images for image-to-video search and caches clips for Pegasus:
CREATE STAGE IF NOT EXISTS SEARCH_UPLOADS
  DIRECTORY  = (ENABLE = TRUE)
  ENCRYPTION = (TYPE = 'SNOWFLAKE_SSE');
Embed Videos with Marengo
AI_MULTI_EMBED with Marengo watches each video and returns a list of segments. Each segment has a 512-dimensional vector for one modality (visual, audio, or transcription) plus its start and end time.
Flatten that output into one row per segment:
CREATE OR REPLACE TABLE VIDEO_EMBEDDINGS AS
WITH raw AS (
    SELECT
        REPLACE(RELATIVE_PATH, '.mp4', '') AS episode,
        AI_MULTI_EMBED(
            'twelvelabs-marengo-embed-3-0',
            TO_FILE('@VIDEO_STAGE', RELATIVE_PATH)
        ) AS emb
    FROM DIRECTORY(@VIDEO_STAGE)
)
SELECT
    episode,
    f.value['embedding']::VECTOR(FLOAT, 512) AS embedding_vec,
    f.value['embedding_option']::STRING      AS modality,
    f.value['start_sec']::FLOAT              AS start_sec,
    f.value['end_sec']::FLOAT                AS end_sec
FROM raw, LATERAL FLATTEN(input => raw.emb['value']) f;
Check what you got:
SELECT modality, COUNT(*) AS segments, COUNT(DISTINCT episode) AS videos
FROM VIDEO_EMBEDDINGS
GROUP BY modality;
aside positive Marengo puts text, images, and video in the same vector space. That's why a text query or an uploaded photo can be matched directly against video segments.
Now pivot to one row per segment with a column per modality, so each modality can get its own index:
CREATE OR REPLACE TABLE VIDEO_SEGMENT_VECTORS AS
SELECT
    episode || '_' || start_sec::STRING AS segment_id,
    episode, start_sec, end_sec,
    MAX(IFF(modality = 'visual',        embedding_vec, NULL)) AS visual_vec,
    MAX(IFF(modality = 'audio',         embedding_vec, NULL)) AS audio_vec,
    MAX(IFF(modality = 'transcription', embedding_vec, NULL)) AS transcript_vec
FROM VIDEO_EMBEDDINGS
GROUP BY episode, start_sec, end_sec;
Index with Multi-Index Cortex Search
Create one Cortex Search service with three vector indexes. Setting query_model tells the service which model produced the vectors, so you can query each index independently or together.
CREATE OR REPLACE CORTEX SEARCH SERVICE VIDEO_MULTI_SEARCH_SVC
  VECTOR INDEXES
    VISUAL_VEC     (query_model = 'twelvelabs-marengo-embed-3-0'),
    AUDIO_VEC      (query_model = 'twelvelabs-marengo-embed-3-0'),
    TRANSCRIPT_VEC (query_model = 'twelvelabs-marengo-embed-3-0')
  PRIMARY KEY (SEGMENT_ID)
  ATTRIBUTES  EPISODE
  WAREHOUSE   = <your_warehouse>
  TARGET_LAG  = '1 day'
AS (
    SELECT SEGMENT_ID, EPISODE, START_SEC, END_SEC,
           VISUAL_VEC, AUDIO_VEC, TRANSCRIPT_VEC
    FROM VIDEO_SEGMENT_VECTORS
);
Search with multi_index_query
Embed the query with the same Marengo model, then pass the vector to the index you want to search. Run these snippets in a Snowflake Notebook, where session comes from get_active_session():
from snowflake.core import Root
from snowflake.snowpark.context import get_active_session

session = get_active_session()
svc = (Root(session).databases["TWELVE_LABS_DEMO"]
       .schemas["VIDEO_INTELLIGENCE"]
       .cortex_search_services["VIDEO_MULTI_SEARCH_SVC"])

query_vec = session.sql("""
  SELECT AI_MULTI_EMBED('twelvelabs-marengo-embed-3-0',
         'Find me a scene where a ship is burning at night'):value[0]['embedding']::ARRAY
""").collect()[0][0]

results = svc.search(
    multi_index_query={"visual_vec": [{"vector": query_vec}]},
    columns=["episode", "start_sec", "end_sec"],
    limit=5,
)
To search what's seen, heard, and said in one request, pass the same vector to every index:
results = svc.search(
    multi_index_query={
        "visual_vec":     [{"vector": query_vec}],
        "audio_vec":      [{"vector": query_vec}],
        "transcript_vec": [{"vector": query_vec}],
    },
    columns=["episode", "start_sec", "end_sec"],
    limit=5,
)
aside positive Image search works the same way: upload the image to
SEARCH_UPLOADSand embed it withAI_MULTI_EMBED('twelvelabs-marengo-embed-3-0', TO_FILE('@SEARCH_UPLOADS', '<image>.jpg')).multi_index_queryaccepts text or vectors, so always embed files first.
aside negative Raw Marengo similarity scores are on different scales per modality (transcript matches typically score much higher than visual or audio). If you want to weight modalities yourself, query each index separately, min-max normalize the scores, and combine them. The sample app does this in its
MARENGO_SEARCHprocedure.
Analyze Video with Pegasus 1.5
Pegasus 1.5 is a video understanding model, available in AI_COMPLETE. Give it a staged video and a natural-language prompt to summarize it, answer questions about it, or extract structured information:
SELECT AI_COMPLETE(
    'twelvelabs-pegasus-1-5',
    'Summarize this video in 3 bullets, then return JSON with the main characters and the timestamp each first appears.',
    TO_FILE('@VIDEO_STAGE', '<your_video>.mp4')
) AS analysis;
There's no frame extraction and no transcription step.
aside negative Preview: video processing with
AI_COMPLETE, includingtwelvelabs-pegasus-1-5, is in Public Preview. See Cortex AI Functions: Multimodal for current status and regional availability.
aside positive Pegasus 1.5 accepts MP4, MOV, AVI, MKV, and WebM files up to 2 hours and 2 GB. See the release note and Cortex AI Functions: Multimodal.
aside positive Pair it with search. To analyze just one search hit, cut its
start_sec/end_secrange to a clip and send the clip to Pegasus. The sample app'sPEGASUS_ANALYZEprocedure does this, caching clips inSEARCH_UPLOADS/clips/.
Deploy the App
The front end is a Next.js app that runs on Snowflake App Runtime (SAR). It's a thin layer over the SQL you just wrote:
- Search: embeds the text or image query with Marengo, runs
multi_index_queryagainstVIDEO_MULTI_SEARCH_SVC, and plays each hit at its timestamp with a presigned URL. - Analyze: sends a video (or a search hit's time range) and a prompt to Pegasus 1.5.
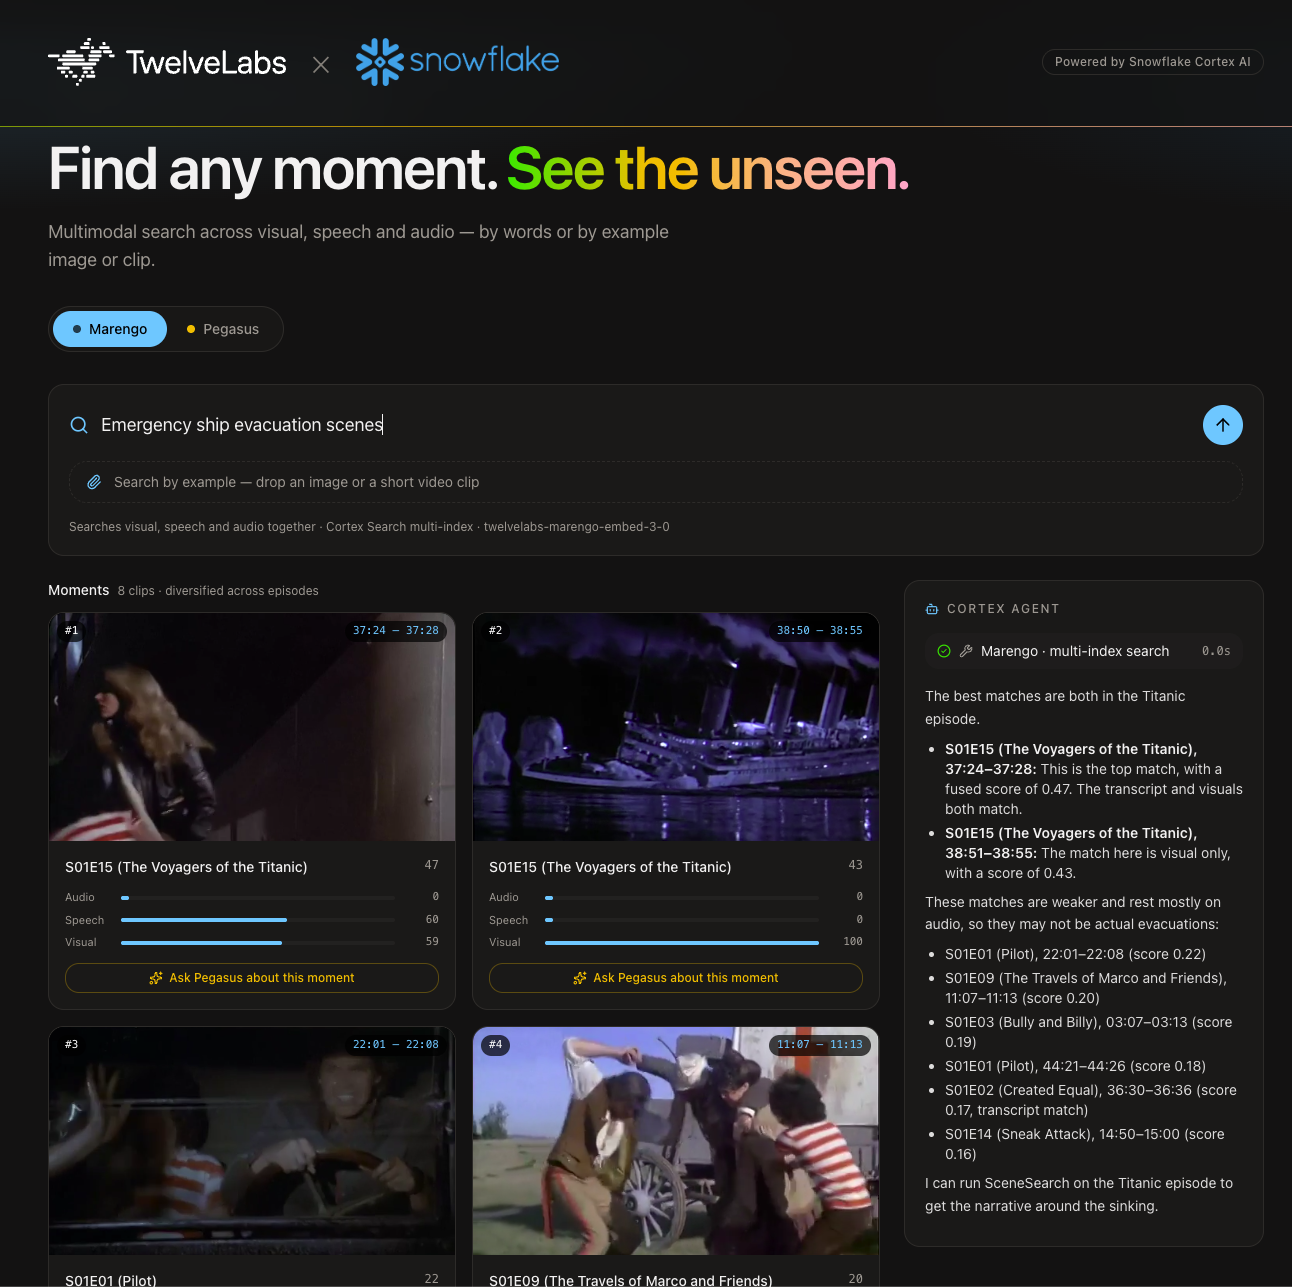
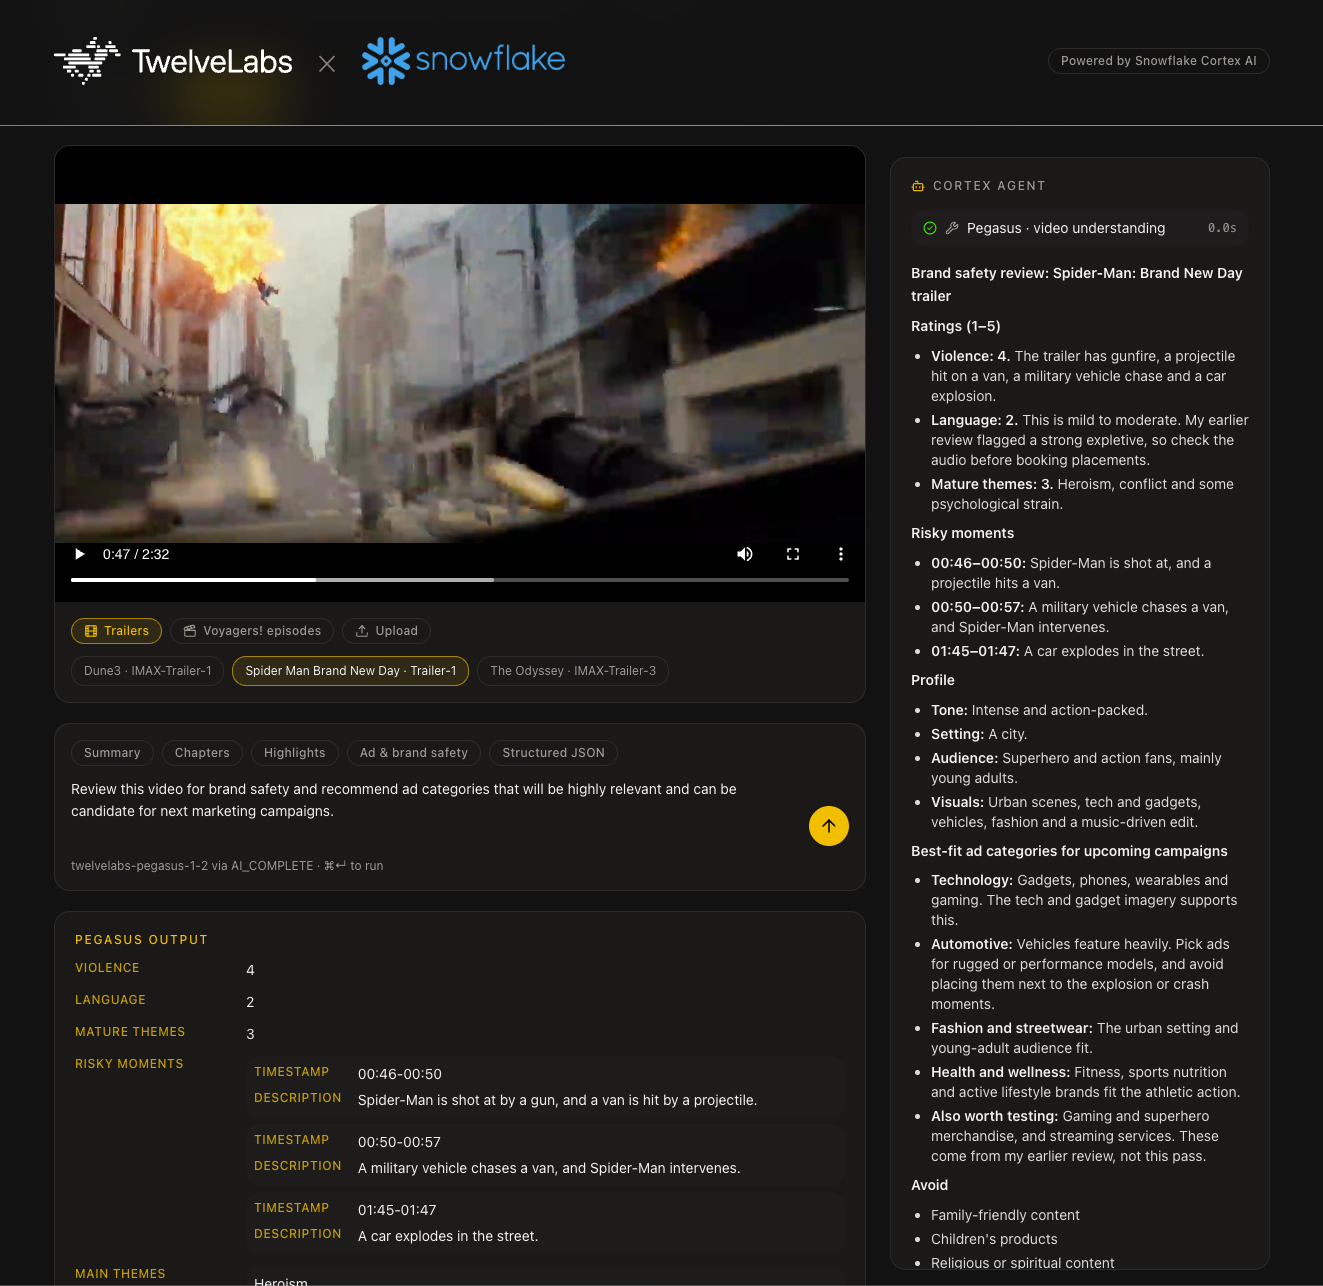
Grab the app source from the src/ folder of this guide. src/setup.sql creates the stored procedures (MARENGO_SEARCH, CLIP_VIDEO, PEGASUS_ANALYZE) and the Cortex Agent the app calls; replace COMPUTE_WH in it with your warehouse, then:
npx degit Snowflake-Labs/sfquickstarts/site/sfguides/src/build-a-video-search-app-with-twelve-labs/src tl-video-studio
cd tl-video-studio
snow sql -f setup.sql  # procedures + Cortex Agent
npm install
npm run dev            # run locally against your default Snowflake connection
snow app setup --app-name=tl_video_studio   # first deploy only: creates the app's deployment config
snow app deploy        # deploy to Snowflake App Runtime
See the src/ README for the grants the app's owner role needs.
Try it
- Search: "Find me a scene where a ship is burning at night", or upload a photo of a location or character.
- Analyze: open a hit and ask "Return JSON with a summary, the main characters, and any historical references."
Clean Up
App Runtime apps keep consuming compute while they run. When you're done, remove the deployed app from the tl-video-studio folder, then drop the demo database (stages, tables, search service, procedures, and agent):
snow app teardown --force
DROP DATABASE IF EXISTS TWELVE_LABS_DEMO;
Conclusion and Resources
You built a video search and analysis app with SQL functions and a small front end on Snowflake App Runtime:
- Marengo 3.0 (
AI_MULTI_EMBED) turned your videos into time-stamped visual, audio, and transcript vectors. - Multi-index Cortex Search made every modality searchable by text or image in one service.
- Pegasus 1.5 (
AI_COMPLETE) answered questions about any video or moment.
What You Learned
- How to embed video, text, and images into one shared vector space with Marengo
- How to build and query a multi-index Cortex Search service with
multi_index_query - How to analyze a video, or a single search hit, with Pegasus
Next Steps
- Run Pegasus over your whole library with a JSON schema and store the output as a metadata table you can join to your business data.
- Wrap search and analysis as tools on a Cortex Agent.
Related Resources
This content is provided as is, and is not maintained on an ongoing basis. It may be out of date with current Snowflake instances
