

Snowflake forData Engineering
Build powerful streaming and batch data pipelines in SQL or Python. Power data engineering for AI and ML, apps and analytics and see 4.6x faster performance while maintaining full governance and control.
Simplify complex data engineering requirements
Build streaming and batch data pipelines on a single platform with the power of declarative pipelines and cost-efficient incremental refresh.
Eliminate unnecessary pipelines with data sharing
Access live, ready-to-use data directly from thousands of data sets and apps via Snowflake Marketplace—all without having to build pipelines.
Code with your language of choice in one optimized engine
Program in Python, SQL and more, then execute with Snowflake’s multi-cluster compute. No separate infrastructure required.
Snowpark for Data Engineering
Use Python to transform raw data into modeled formats for data pipelines
Snowpark Price Performance: Customer Results
Customers see an average of 4.6x faster performance and 35% cost savings with Snowpark over managed Spark.1
Scalable Data Pipelines
Transformations on data connected to your data lake, warehouse, or Iceberg tables in Snowflake.
How It Works
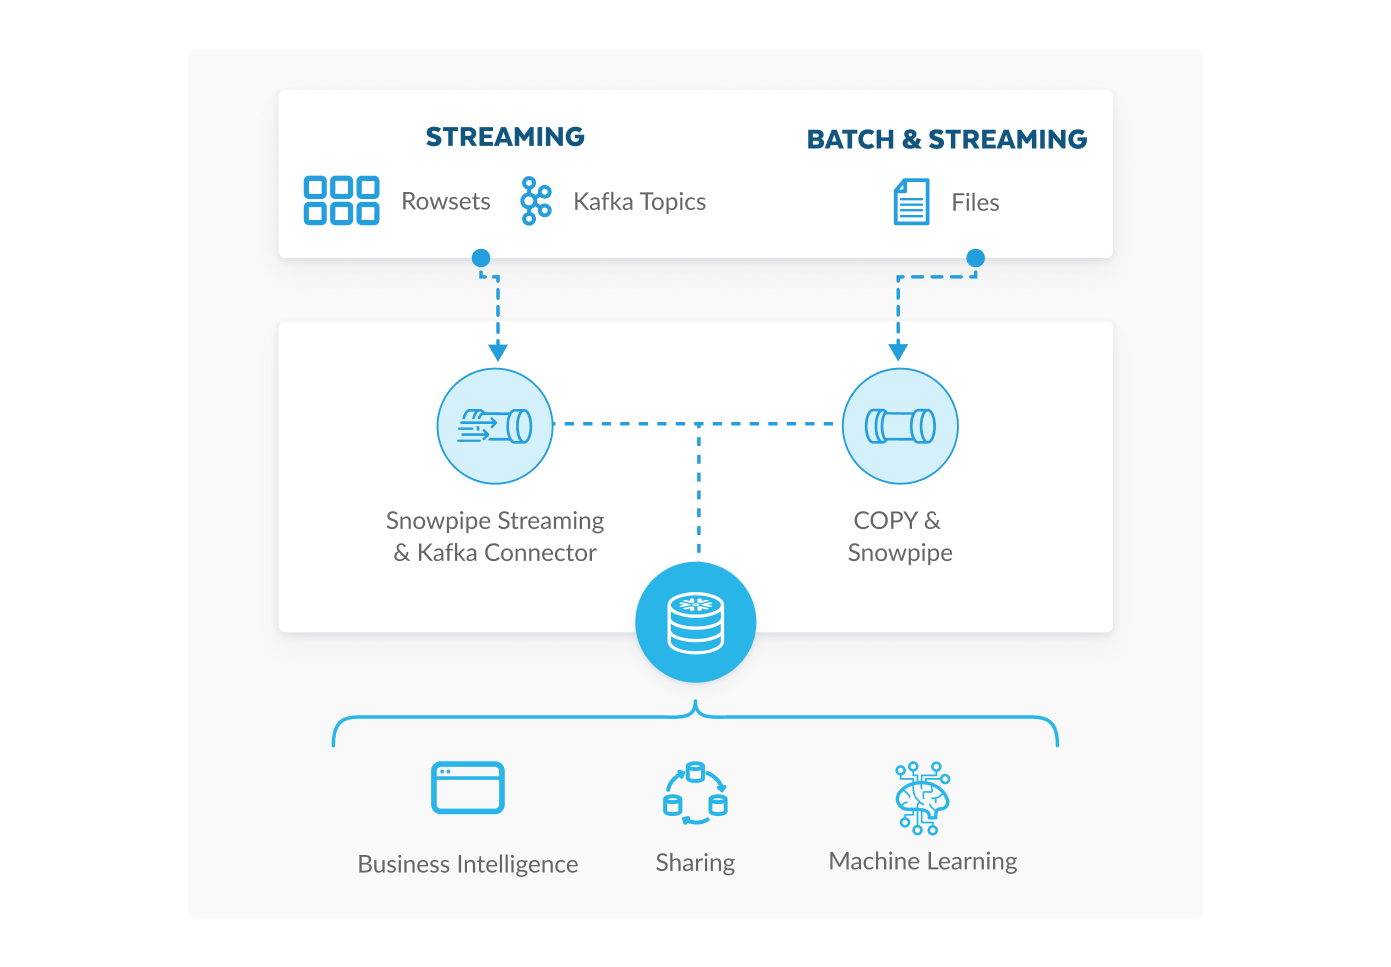
Stream Data With <10-Second Latency
Often kept separate, streaming and batch systems are typically complex to manage and costly to scale. But Snowflake keeps things simple by handling both streaming and batch data ingestion and transformation in a single system.
Stream row-set data in near real time with single-digit latency using Snowpipe Streaming, or auto-ingest files with Snowpipe. Both options are serverless for better scalability and cost-efficiency.
Adjust Latency With a Single Parameter Change
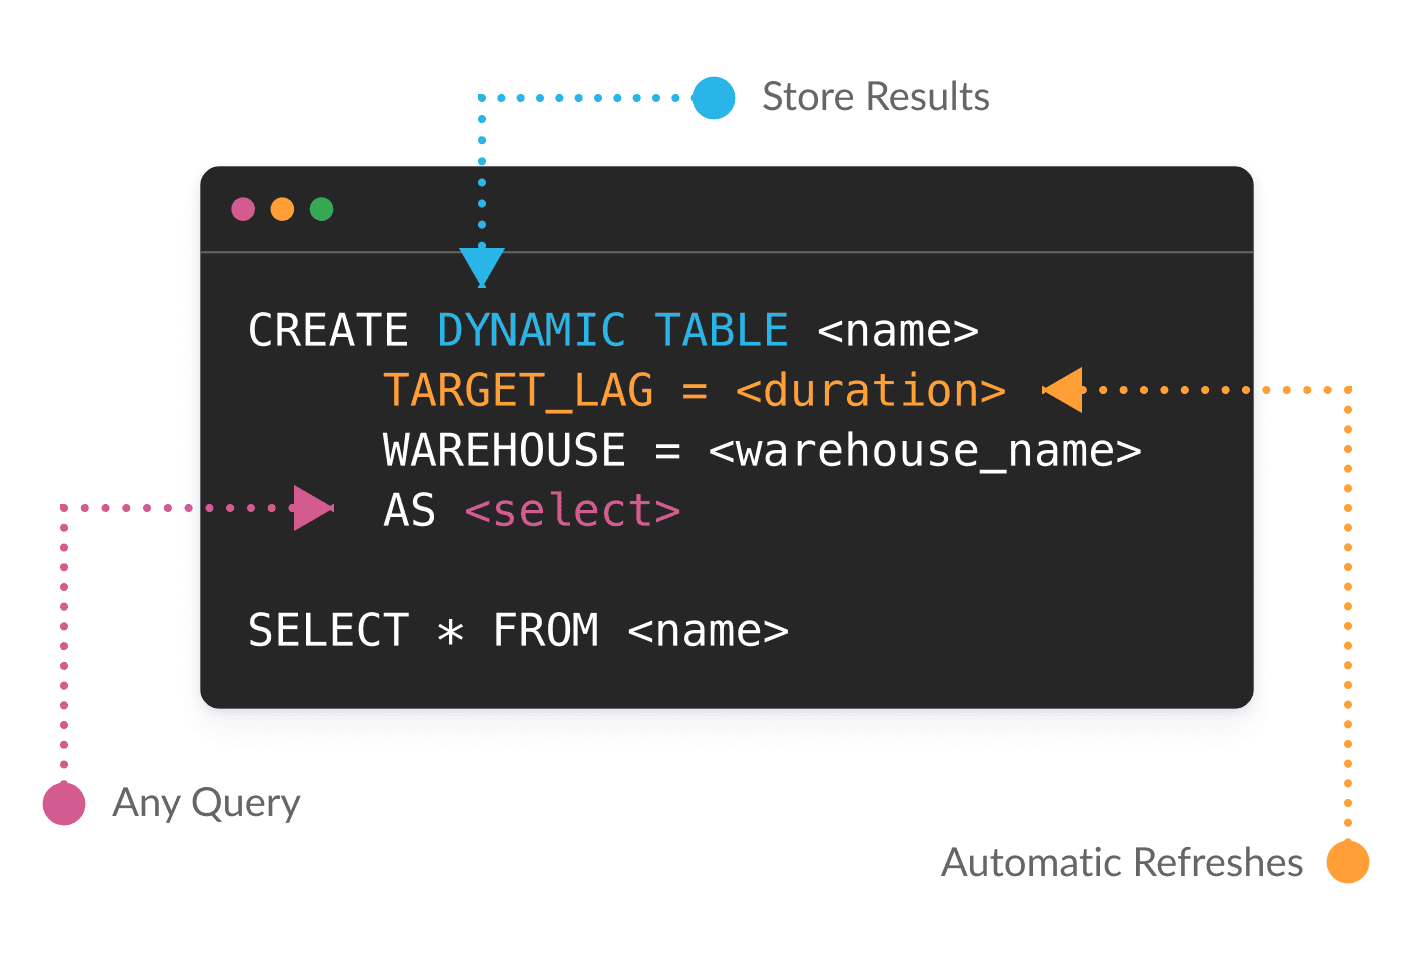
With Dynamic Tables, you can use SQL or Python to declaratively define data transformations. Snowflake will manage the dependencies and automatically materialize results based on your freshness targets. Dynamic Tables can operate only on data that has changed since the last refresh to make high data volumes and complex pipelines simpler and more cost-efficient.
As business needs change, you can easily adapt by making a batch pipeline into a streaming pipeline with a single latency parameter change.
Power Data Engineering for Analytics, AI/ML and Applications
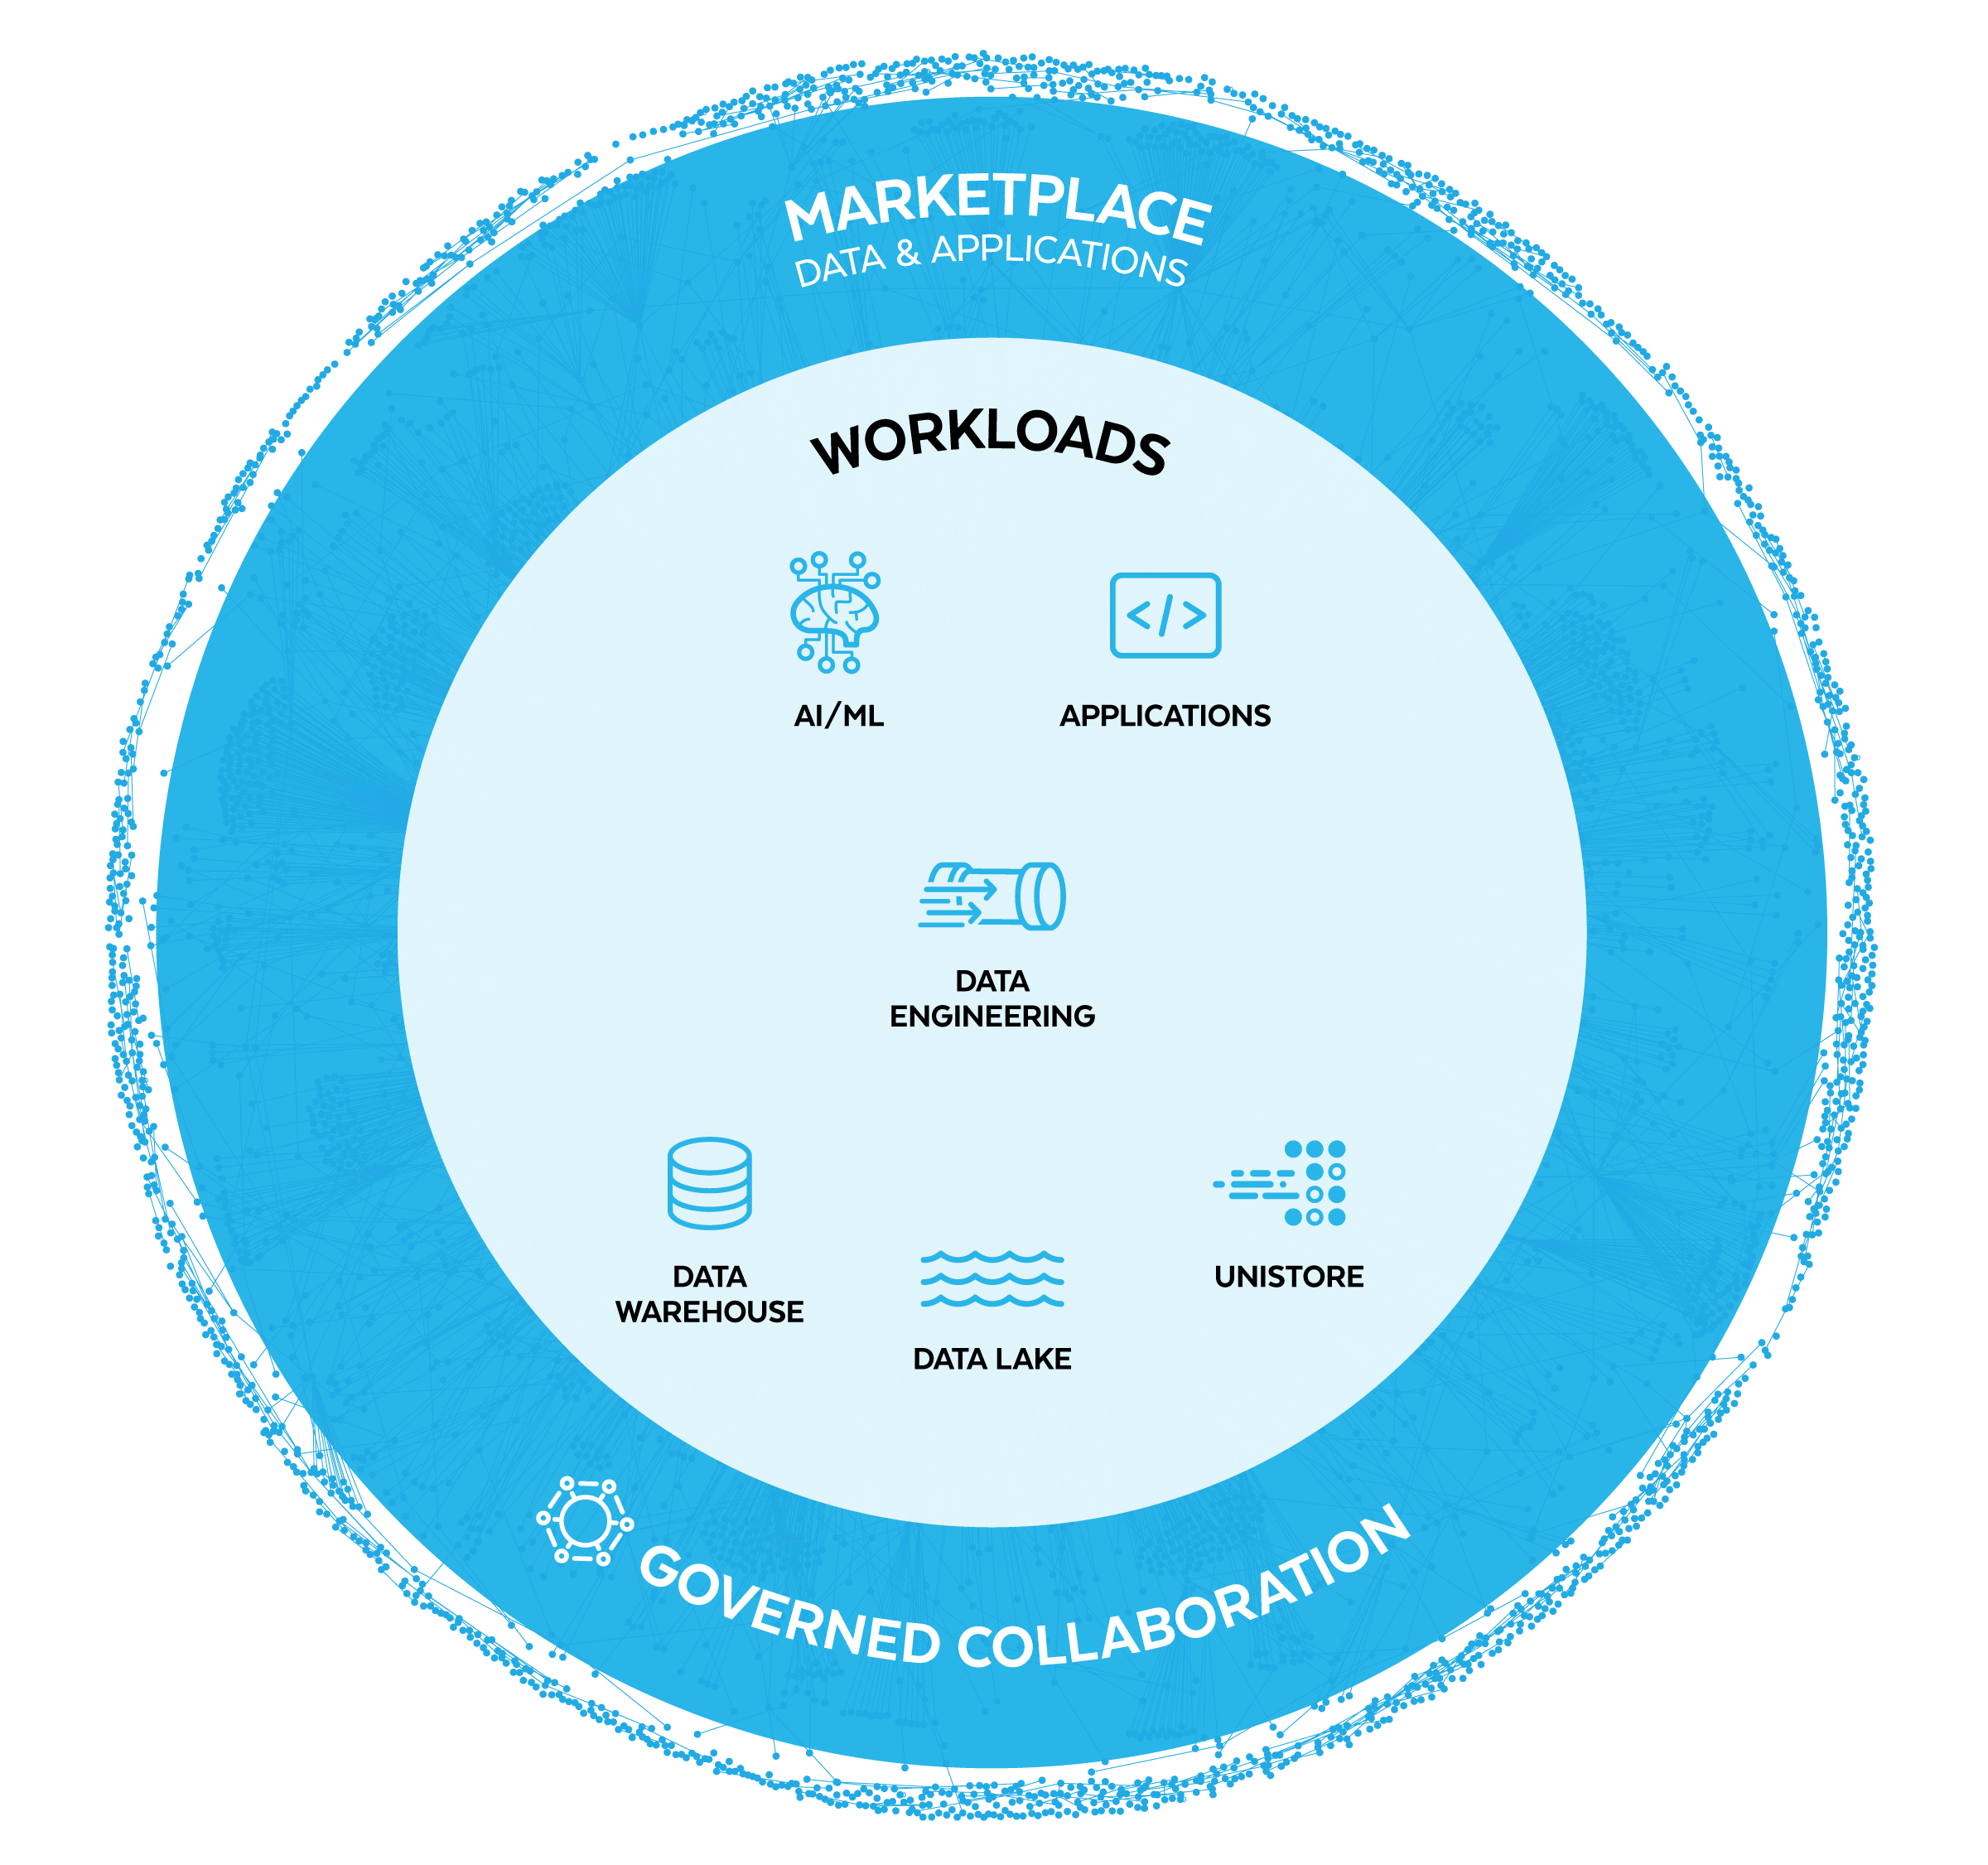
Bring your workloads to the data to streamline pipeline architecture and eliminate the need for separate infrastructure.
Bring your code to the data to fuel a variety of business needs—from accelerating analytics to building apps to unleashing the power of generative AI and LLMs. With Snowpark’s libraries and runtimes, this code can be in whichever language you prefer, including Python, Java or Scala.
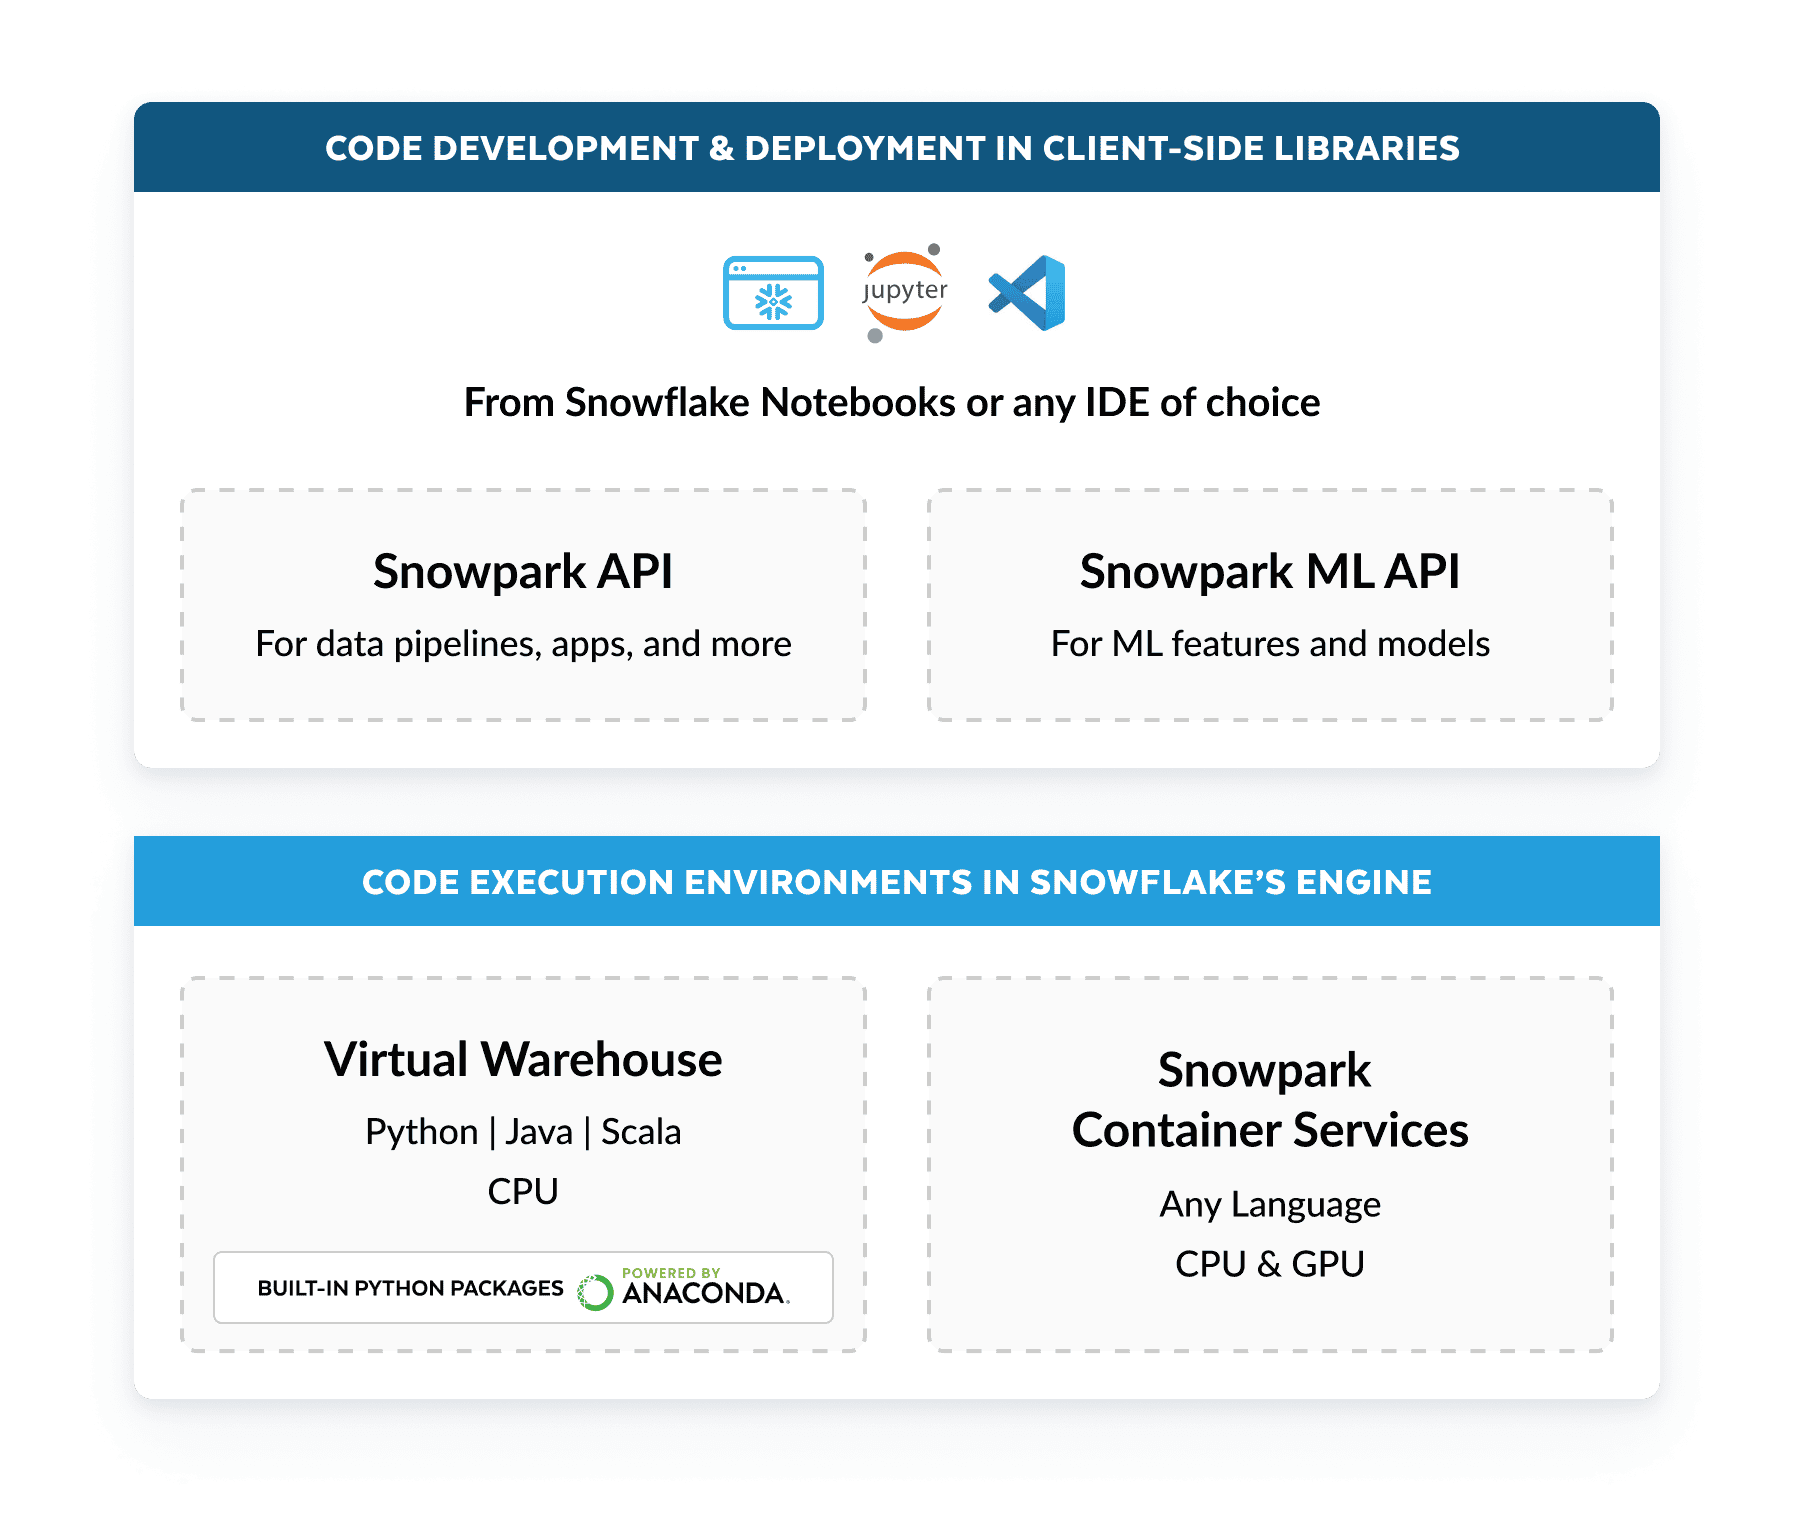
See 4.6x Faster Performance and 35% Cost Savings—Without Compromising Governance
Run Python and other programming code next to your data in Snowflake to build data pipelines. Automatically push down processing in multi-lingual runtimes built right into Snowflake’s elastic compute engine.
JUMPSTART DATA ENGINEERING WITH FEWER DATA PIPELINES
With the AI Data Cloud, you’ll have a vast network of data and applications at your fingertips.
Easily access and distribute data and applications with direct access to live data sets from Snowflake Marketplace, which reduces the costs and burden associated with traditional extract, transform and load (ETL) pipelines and API-based integrations. Or, simply use Snowflake’s native connectors to bring data in frictionlessly, with no additional license cost.


STREAMLINE YOUR PATH TO PRODUCTION WITH BUILT-IN DEVOPS FEATURES
Directly import project configurations and pipelines from Git, triggering deployments. Maintain database consistency with automated change management (create, alter, execute) into production environments. Manage Snowflake resources programmatically using Python APIs.* Automate tasks within your CI/CD pipeline (like GitHub Actions) with the Snowflake CLI. This empowers collaboration, version control and seamless integration directly on Snowflake or with your existing DevOps tools. And gain effortless observability with Snowflake Trail.
*In public preview
OUR CUSTOMERS
leaders use snowflakefor data engineering


Eliminate SiloedDevelopment
Bring more workloads, users and use cases directly to your data—all within the AI Data Cloud.


